Command Line Interface since 0.8a.8
Test Junkie ships with a tj command that lets you run tests, audit your suite, and persist configuration — no extra code required.
tj -h lists every sub-command. Each sub-command has its own help too — e.g. tj run -h or tj audit suites -h. Use tj version to confirm the installed version and active Python interpreter.Reading the output since 0.9a6
All three commands print in the same style. Colors carry the same meaning everywhere: green passed or saved, yellow failed, red an error, blue skipped or restored, orange ignored or missing, gray cancelled. Colors are on in a terminal and in GitHub Actions; set NO_COLOR to turn them off, or FORCE_COLOR to keep them when output goes to a file. Errors print a red ERROR line with what to type instead, and exit with code 120.
tj run new since 0.8a.8
Executes tests without requiring any additional code. Accepts the same options as Runner.run(), all settable from the terminal:
# Run everything under --sources with default settings
tj run

# 2 suite threads, 10 test threads, scoped to 2FA and OAuth components
tj run -c 2FA OAuth -T 10 -S 2

# Only problems and the result line, resource monitoring, HTML report
tj run -q -m --html-report "/path/to/report.html"

# One line per test, and test output shown live (for breakpoint() / pdb)
tj run -p --no-capture

# Load from a config file (explicit CLI args still take precedence)
tj run --config "/path/to/your_config.cfg"
These examples assume --sources is already saved in your config (see tj config below). Full reference: tj run -h.
What a run prints since 0.9a6
A run starts with a short header: the Test Junkie and Python versions, what was found and how it will run. Each suite then gets a progress bar that fills as its tests finish. The bar takes the color of the worst result in the suite so far: red if a test errored, yellow if one failed, orange if one was ignored, green otherwise. When the run ends you get the problems, a summary table and the result. A + after the test count, as in 16+ tests, means some tests get their parameters from a function, so the real count is known only when they run.
$ tj run -s tests
Test Junkie 0.9a6 · Python 3.12.5 · Windows 11
  tests    tests · 5 suites, 44 tests · found in 0.14s
  mode     sequential

LoginSuite     tests/ui/login.py     [||||||||||||||||||||||||]  10/10  4.12s
CheckoutSuite  tests/ui/checkout.py  [||||||||||||||||||||||||]  11/11  3.05s
PaymentsSuite  tests/api/payments.py [||||||||||||||||||||||||]    6/6  0.03s
SearchSuite    tests/api/search.py   [||||||||||||||||||||||||]    9/9  0.84s
ReportsSuite   tests/api/reports.py  [||||||||||||||||||||||||]    8/8  1.20s

Total                                [||||||||||||||||||||||||]  44/44  100%  9.24s

Problems 4 ─────────────────────────────────────────────────────────────────────

 FAIL  LoginSuite.rejects_bad_password  [user='admin']
       tests/ui/login.py:42 · failed all 3 runs · 1.83s

  Runs
    #1  ERROR  0.61s  TimeoutException: login form not loaded after 10s
    #2  FAIL   0.60s  AssertionError: expected 'Invalid password', got ''
    #3  FAIL   0.62s  AssertionError: expected 'Invalid password', got ''

  Run #1  traceback
  │ tests/ui/login.py:38 in rejects_bad_password
  │     page = LoginPage.open(self.driver)
  │ tests/ui/pages.py:17 in open
  │     WebDriverWait(driver, 10).until(form_visible)
  │ selenium.common.exceptions.TimeoutException: login form not loaded after 10s

  Runs #2–#3  same traceback both times
  │ tests/ui/login.py:42 in rejects_bad_password
  │     assert page.error_text() == "Invalid password"
  │ AssertionError: expected 'Invalid password', got ''

  Output  run #3
  │ opening https://staging.example.com/login
  │ submitting form as admin

  Log  run #3
  │ WARNING  selenium.webdriver.remote  element #error not visible after 5.0s


 ERROR  ReportsSuite.export_csv
        tests/api/reports.py:88 · 1 run · 0.12s

  Traceback
  │ tests/api/reports.py:88 in export_csv
  │     rows = client.get("/reports/export").json()
  │ tests/api/client.py:31 in get
  │     return self.session.get(self.base + path, timeout=5)
  │ requests.exceptions.ConnectionError: HTTPConnectionPool(host='localhost', port=8080):
  │ Max retries exceeded with url: /reports/export

 IGNORED  PaymentsSuite  whole suite
          tests/api/payments.py:14 · @beforeClass failed · 6 tests not run

  Traceback
  │ tests/api/payments.py:14 in before_class
  │     self.gateway = Gateway.connect(sandbox=True)
  │ tests/api/gateway.py:22 in connect
  │     raise GatewayUnavailable(self.url)
  │ GatewayUnavailable: https://sandbox.pay.example.com is not responding


 IGNORED  SearchSuite.filters_by_date
          tests/api/search.py:57 · bad parameters · not run

  │ BadParameters: "parameters" in @test() must be a list, but found: dict
  │ https://www.test-junkie.com/documentation/#test-decorator

Summary ────────────────────────────────────────────────────────────────────────

  Suite             Pass  Fail  Error  Ignore  Skip  Cancel     Time
  LoginSuite           9     1      ·       ·     ·       ·    4.12s
  CheckoutSuite       10     ·      ·       ·     1       ·    3.05s
  PaymentsSuite        ·     ·      ·       6     ·       ·    0.03s
  SearchSuite          8     ·      ·       1     ·       ·    0.84s
  ReportsSuite         6     ·      1       ·     1       ·    1.20s
  ──────────────────────────────────────────────────────────────────
  Total               33     1      1       7     2       ·    9.24s
  44 tests           75%    2%     2%     16%    5%

────────────────────────────────────────────────────────────────────────────────

 FAILED   exit code 1
- Problems lists every test that failed, errored or was ignored. A retried test shows each run with its result and error, and runs that failed the same way share one traceback. Tracebacks show your own code only, as
file:line in functionwith the line under it; the full traceback is still in the HTML report. - A suite whose
@beforeClassfailed is one entry with that traceback, not one per test. - Summary has a row per suite and a column per result. Zeros are dots, so the numbers that matter stand out.
- On a terminal the bars are redrawn in place. In CI logs or a file, each suite prints one line when it finishes.
Test output since 0.9a6
What your tests print and log is captured. It's shown under Problems for the tests that didn't pass, and dropped for the ones that did. To see it live instead, for example to use breakpoint() or pdb, add --no-capture. Loggers that set propagate = False are captured too.
| Option | What it prints |
|---|---|
tj run | Header, a progress bar per suite, problems, summary and the result |
-p / --per-test | One line per test instead of the bars |
-q / --quiet | Only the problems and one result line with the counts. A passing run prints one line |
--no-capture | Test output as it happens, printed above the progress bars |
Runner.run(quiet=True) | Nothing at all, for scripts that read the results themselves |
$ tj run -s tests -q
Problems 4 ─────────────────────────────────────────────────────────────────────

 FAIL  LoginSuite.rejects_bad_password  [user='admin']
       tests/ui/login.py:42 · failed all 3 runs · 1.83s
  … runs, tracebacks, output and log as in the default view …

 ERROR  ReportsSuite.export_csv
        tests/api/reports.py:88 · 1 run · 0.12s
  … traceback …

 IGNORED  PaymentsSuite  whole suite
          tests/api/payments.py:14 · @beforeClass failed · 6 tests not run
  … traceback …

 IGNORED  SearchSuite.filters_by_date
          tests/api/search.py:57 · bad parameters · not run
  … error …

 FAILED   1 failed, 1 error, 7 ignored · 33 passed, 2 skipped · 9.21s · exit code 1

$ tj run -s tests/ui/checkout.py -q
 PASSED   10 passed, 1 skipped · 3.05s
$ tj run -s tests -p
Test Junkie 0.9a6 · Python 3.12.5 · Windows 11
  tests    tests · 5 suites, 44 tests · found in 0.14s
  mode     sequential · one line per test

tests/ui/login.py::LoginSuite
  PASSED   accepts_valid_user                                    0.41s  [  2%]
  PASSED   accepts_valid_user[user='qa_basic']                   0.38s  [  5%]
  PASSED   remembers_session                                     0.52s  [  7%]
  …
  FAILED   rejects_bad_password[user='admin']        run 3/3     0.62s  [ 24%]
  PASSED   logout_clears_cookie                                  0.29s  [ 26%]

tests/ui/checkout.py::CheckoutSuite
  PASSED   adds_item_to_cart                                     0.33s  [ 29%]
  …
  SKIPPED  pays_with_paypal                          skip=True          [ 45%]
  PASSED   applies_coupon                            passed on run 2    0.71s  [ 53%]
  …
Stopping a run with Ctrl+C since 0.9a6
The first Ctrl+C cancels the run cleanly. No new tests start and nothing is retried, and every test that hasn't started is marked cancelled. Tests already running finish their current run: Python has no safe way to stop a running thread. In a run without threads, the test that's running is stopped right away. Your cleanup still runs (@afterTest, @afterClass, rules), then the summary and reports are written. While it waits, Test Junkie shows what's still running and for how long, so a hung test is easy to spot.
Test Junkie 0.9a6 · Python 3.12.5 · Windows 11
  tests    tests · 5 suites, 44 tests · found in 0.14s
  mode     parallel · 4 suite threads · 10 test threads

LoginSuite     tests/ui/login.py     [||||||||||||||··········]   6/10  cancelling
CheckoutSuite  tests/ui/checkout.py  [|||||||||||·············]   5/11  cancelling
PaymentsSuite  tests/api/payments.py [||||||||||||||||||||||||]    6/6  0.03s
SearchSuite    tests/api/search.py   [||||||||||||||||||||||||]    9/9  0.84s
ReportsSuite   tests/api/reports.py  [||||||||||||||||||||||||]    8/8  1.20s

Total                                [|||||||||||||||||||·····]  34/44   77%  1.9s

 CANCELLING   Ctrl+C received. No new tests will start and nothing is retried.
               Waiting for 3 tests in progress to finish, then cleanup (@afterTest, @afterClass, rules).
                 › LoginSuite.remembers_session  running 1.2s
                 › CheckoutSuite.applies_coupon  running 0.4s
                 › CheckoutSuite.pays_with_card  running 0.1s
               Press Ctrl+C again to stop immediately. Cleanup and reports will be skipped.
If you press Ctrl+C again, the run stops immediately. Cleanup and reports are skipped, so browsers or other resources the running tests opened may stay open.
 CANCELLING   Ctrl+C received. No new tests will start and nothing is retried.
               Waiting for 1 test in progress to finish, then cleanup (@afterTest, @afterClass, rules).
                 › LoginSuite.remembers_session  running 31.4s
               Press Ctrl+C again to stop immediately. Cleanup and reports will be skipped.
^C
 STOPPED   Second Ctrl+C: stopped immediately.
            1 test was still running: LoginSuite.remembers_session (31.4s).
            Cleanup and reports were skipped. Browsers or other resources it opened may still be open.
            exit code 130
Runner.cancel() cancels the same way from code. Tests in suites that never started are listed as cancelled in every mode (-S/-T too), and the run ends [CANCELLED] with exit code 12. When the run was cancelled by Ctrl+C, Runner.run() raises KeyboardInterrupt after the reports are written, so your script still sees the interrupt.
Exit codes since 0.9a2
| Code | Condition |
|---|---|
| 0 | All tests passed |
| 1 | Any test failed, errored, or was ignored due to a lifecycle decorator failure; no tests ran; no suites were found. Not when the run was cancelled: that is 12 |
| 12 | The run was cancelled (Ctrl+C or Runner.cancel()), even if tests had already failed; it ends [CANCELLED]. Cleanup ran and the reports were written |
| 120 | The run itself failed, for example a custom listener raised an error. The traceback is printed after the summary |
| 130 | Stopped with a second Ctrl+C; cleanup and reports were skipped |
Picking tests since 0.9a6
-t takes test names, Suite.test names and patterns. -x skips suites by class name or pattern. Tag options read the same in every command: -k --tags-any / -l --tags-all for any or all of the tags, -g --skip-tags-any / -j --skip-tags-all to skip them.
# every test whose name starts with login_
tj run -t "login_*"

# one test in one suite
tj run -t CheckoutSuite.applies_coupon

# everything except the legacy suites
tj run -x "Legacy*"

# tests tagged smoke and fast
tj run -l smoke fast
Options use dashes now (--test-multithreading-limit). The old spellings, like --test_multithreading_limit, still work but aren't listed in -h.
Random order and --seed since 0.9a6
When a suite uses @Suite(order=TestOrder.RANDOM), the header prints the seed of the order. Pass it back with --seed to run the tests in exactly the same order, e.g. to reproduce a failure that depends on order.
Test Junkie 0.9a6 · Python 3.12.5 · Windows 11
  tests    tests · 1 suite, 8 tests · found in 0.00s
  mode     sequential
  order    random · seed 4242  repeat this order with --seed 4242
Retries for one run since 0.9a6
These options change retries for one run, without touching the code:
--retry Nlets every failing test run up to N times, whatever its@test(retry=)says.--no-retryruns every test and suite once, e.g. to see the real failure rate.--retry-policy module:Classgives every test without a retry of its own a retry policy.
The header shows which one is on.
Flaky tests in one run new since 0.9a8
A test that failed and then passed on a retry is flaky. It counts as passed unless you ask otherwise:
- No flag: with
-pits line readsPASSEDwithpassed on run 2, and the run passes. --flag-flaky: with-pit shows asFLAKY, and it is listed after the summary with the run it passed on and the first error. The run still passes.--fail-on-flaky: the same, plus a Problems entry for each flaky test (every run and the traceback of each failed run), and the run fails with exit code 1.
$ tj run -s tests -p
...
CheckoutSuite  tests\checkout.py
  PASSED     adds_item_to_cart                                                  0.00s  [ 33%]
  PASSED     pays_with_card                                passed on run 2      0.00s  [ 66%]
  PASSED     shows_receipt                                                      0.00s  [100%]
...
 PASSED   exit code 0
$ tj run -s tests -p --flag-flaky
...
CheckoutSuite  tests\checkout.py
  PASSED     adds_item_to_cart                                                  0.00s  [ 33%]
  FLAKY      pays_with_card                                passed on run 2      0.00s  [ 66%]
  PASSED     shows_receipt                                                      0.00s  [100%]
...
Flaky 1 ────────────────────────────────────────────────────────────────────────

  CheckoutSuite.pays_with_card   passed on run 2
      TimeoutError: payment page not loaded after 10s

 PASSED   exit code 0
$ tj run -s tests -p --fail-on-flaky
...
  FLAKY      pays_with_card                                passed on run 2      0.00s  [ 66%]
...
Problems 1 ─────────────────────────────────────────────────────────────────────

 FLAKY  CheckoutSuite.pays_with_card
        tests\checkout.py:17 · passed on run 2 (--fail-on-flaky) · 0.00s

  Runs
    #1  ERROR   0.00s  TimeoutError: payment page not loaded after 10s
    #2  PASS    0.00s

  Run #1  traceback
  │ tests\checkout.py:17 in pays_with_card
  │     raise TimeoutError("payment page not loaded after 10s")
  │ TimeoutError: payment page not loaded after 10s
...
Flaky 1 ────────────────────────────────────────────────────────────────────────

  CheckoutSuite.pays_with_card   passed on run 2
      TimeoutError: payment page not loaded after 10s

 FAILED   1 flaky test (--fail-on-flaky)  exit code 1
Throttling, ramp-up and truncation new since 0.9a8
Pace a run so it doesn't flood the system under test, and decide how much of each failure is kept.
| Option | What it does |
|---|---|
| Pace | |
--test-throttling S | At least S seconds between two test starts, across the run. Only when tests run in parallel (-T above 1); a suite's @Suite(throttling=) wins for its own tests. Default 0, no spacing |
--suite-throttling S | At least S seconds between two suite starts, across the run. Only when suites run in parallel (-S above 1). Default 0 |
--ramp-up S | Grows the suite and test thread limits (-S / -T) from 1 to their full value over S seconds. Default 0, full limits from the start |
| Failure size | |
--traceback-limit N | Keeps at most N characters of each traceback. Default 3000 |
--message-limit N | Keeps at most N characters of each error message. Default 3000 |
--truncate MODE | MODE is what to keep when over the limit: top cuts the start, bottom cuts the end, middle keeps both ends (default) |
Save any of them with tj config update so every run uses them. More in Throttling & Pools and Truncation.
JSON report, and report folders since 0.9a6
--json-report writes every result as JSON: each test with its status, whether it was flaky and every run with its runtime and error, plus totals and the seed. All three report options take a file or a folder.
| Option | Given a folder, writes |
|---|---|
--html-report PATH | report.html |
--xml-report PATH | report.xml |
--json-report PATH | report.json |
# all three reports into one folder
tj run --html-report out/ --xml-report out/ --json-report out/
{
  "test_junkie": "0.9a8", "runtime": 0.42, "seed": 4242,
  "totals": {"total": 3, "success": 2, "fail": 1, …},
  "suites": [
    {
      "name": "FlakySuite", "module": "flaky", "status": "fail", "runtime": 0.42,
      "tests": [
        {
          "name": "always_fails", "parameter": null, "suite_parameter": null,
          "status": "fail", "flaky": false, "meta": {},
          "runs": [
            {"status": "fail", "runtime": 0.0, "error": "AssertionError: nope", "retry": null, "meta_set": {}}
          ]
        },
        …
      ]
    }
  ]
}
Run again what didn't pass since 0.9a7
--rerun FILE runs only the tests that failed, errored or were ignored in a --json-report, down to the parameter. The header shows how many. See Rerun.
tj run --json-report reports/
tj run --rerun reports/report.json
GitHub Actions annotations since 0.9a6
On GitHub Actions, tj run also prints an ::error line for every failed, errored or ignored test, so GitHub marks the failing line in the pull request. Nothing to set up: it's on when GITHUB_ACTIONS is set, which GitHub does.
::error file=tests/checkout.py,line=42,title=CheckoutSuite.applies_coupon::FAIL: AssertionError: expected 90, got 100
When a saved config is used since 0.9a6
If any setting comes from your saved config (see tj config), the header says so: where the config is and which settings it applied. Anything you pass on the command line wins and isn't listed.
Test Junkie 0.9a6 · Python 3.12.5 · Windows 11
  tests    tests · 1 suite, 6 tests · found in 0.00s
  mode     parallel · 1 suite thread · 4 test threads
  filters  tags any smoke
  config   C:\Users\you\AppData\Local\Test-Junkie\Test-Junkie\.tj.cfg
           run_on_match_any smoke · sources tests · test_multithreading_limit 4
Resource chart (-m) since 0.9a6
With -m / --monitor-resources, Test Junkie samples CPU and memory four times a second while the tests run, and charts them after the Summary. CPU is the filled area and memory the line, both on one 0–100% axis. Every test is a dot at the moment it finished, in its result color, and the row under the dots shows when each suite ran, so you can see what was running when the machine got busy. The key line says which suites were running at the CPU peak.
  44 tests           75%    2%     2%     16%    5%

────────────────────────────────────────────────────────────────────────────────

Resources CPU and memory, whole machine ────────────────────────────────────────

  █ CPU     avg 52% · peak 81% at 3.2s · during LoginSuite
  ━ Memory  avg 58% · peak 64% at 7.0s

   100% ┤
        ┤  ▂▂                ▄▄▁▁
    75% ┤  █████▂▂     ▄▆▆  ▅████▆▂▂      ━━━━━━━━━━━━━━━━━
        ┤  ████━━━━━━━━━━━━━━━━━━━━━━━━━━━  ▁▁             ━━━━━━━━━━
    50% ┤━━━━━━█████▆▁▁███████████████████████▂               ▁▅▅████
        ┤  ████████████████████████████████████▆▆▄▄▄██▇▆▆▆▆▅▆▆███████
    25% ┤  ██████████████████████████████████████████████████████████
        ┤▆▅██████████████████████████████████████████████████████████
     0% ┼────────────────────────────────────────────────────────────
   tests   ● ●  ●  ● ●  ●  ●  ● ●  ● ● ●● ● ● ● ●● ● ● ●●●●●●●●●●●●●●
                                                       ●● ●●   ●
                                                       +
  suites ├Login────────────────────├Checkout───────────├Sear…├Reports
         0s          2s           4s           6s           8s   9.2s

  ● passed  ● failed  ● error  ● skipped  ● ignored  ● cancelled
When suites or tests run in threads, every suite thread gets its own lane, so overlapping suites stay readable, and a running row shows how many tests were in progress at each moment, out of your test threads:
Resources CPU and memory, whole machine ────────────────────────────────────────

  █ CPU     avg 72% · peak 83% at 0.05s · during Login, Checkout, Search, Reports
  ━ Memory  avg 70% · peak 74% at 2.30s
  ▆ tests running at once, out of 10 test threads

   100% ┤
        ┤ ▅▅▄▃    ▃▁▄▄▁▄▄  ▄▁▄▁  ▂▃   ▄▃     ▃ ▂▁ ▃ ▂ ▁▁
    75% ┤██████━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━
        ┤━━━━━━████████████████████████████████████████████▇▄█ ▁
    50% ┤███████████████████████████████████████████████████████▄
        ┤████████████████████████████████████████████████████████▃
    25% ┤█████████████████████████████████████████████████████████▇▇▅
        ┤████████████████████████████████████████████████████████████
     0% ┼────────────────────────────────────────────────────────────
  running█████████████████████████████████████████████████▇▆▆▆▅▅▅▄▂▂▂  peak 10 of 10
   tests ●●              ●    ●●●  ● ●●    ●● ● ●● ●●●● ●●●  ●  ●● ●●
         ●                    ●●●           ●      ● ●   ●●     ●●
         ●                    ●
         +
  suites ├Login───────────────────────
         ├Checkout─────────────────────────────────────────
         P├Reports───────────────────────────────────────────────────
         ├Search───────────────────────────────────────────
         0s        0.5s       1s         1.5s       2s          2.74s

  ● passed  ● failed  ● error  ● skipped  ● ignored  ● cancelled
- The numbers are for the whole machine, not just Test Junkie. They're the same samples the HTML report charts.
- The chart is as wide as your terminal. In CI logs and files it prints at 60 columns, without colors.
-qleaves it out. - A run shorter than a quarter of a second is too short to sample, and says so.
tj audit since 0.8a.8
Scans your codebase and aggregates test data based on the query you give it, without running anything. Useful for coverage reads, Git hooks, or finding gaps in metadata. Pick a view, and every block in it is one owner, suite, feature, component or tag:
# All tests broken down by owner
tj audit owners

# Tests missing a tag
tj audit tags --no-tags

# Owners for specific components
tj audit owners --components 2FA OAuth

# Each component split by feature
tj audit components --by-features

# Suites missing an owner
tj audit suites --no-owners
Views: suites, features, components, tags, owners. They all take the same options. tj audit conflicts lists every pair of tests that must not run together. Full reference: tj audit suites -h.
What an audit prints since 0.9a6
One block per entry, biggest first, with its share of all tests and what it's made of. Missing metadata reads none, and the Gaps section at the end counts the tests that lack each kind, with the command that lists them.
Test Junkie 0.9a6 · Python 3.12.5 · Windows 11
  tests    tests · 5 suites, 13 tests · found in 0.00s
  audit    suites

LoginSuite                          4 tests ·  31%  [|||||···········]
  feature      Accounts
  owners       qa-team 4
  components   auth 4
  tags         regression 2 · smoke 2

CheckoutSuite                       3 tests ·  23%  [||||············]
  feature      Billing
  owners       checkout-team 3
  components   payment 3
  tags         regression 2 · smoke 1

PaymentsSuite                       2 tests ·  15%  [||··············]
  feature      Billing
  owners       checkout-team 2
  components   payment 1 · refunds 1
  tags         regression 2

ReportsSuite                        2 tests ·  15%  [||··············]
  feature      Analytics
  owners       none 2
  components   reports 1 · none 1
  tags         none 2

SearchSuite                         2 tests ·  15%  [||··············]
  feature      Catalog
  owners       search-team 2
  components   search 2
  tags         smoke 1 · none 1

Gaps 3 ─────────────────────────────────────────────────────────────────────────

  2 tests  have no owner         tj audit suites --no-owners
  1 test   has  no component     tj audit suites --no-components
  3 tests  have no tags          tj audit suites --no-tags

────────────────────────────────────────────────────────────────────────────────

13 tests · 5 suites · 4 features · 3 owners · 5 components · 2 tags
- With a filter (
--no-owners,-o,-c,-f,-l…) each block also lists its tests by name, up to 10, so you can go straight to them. --by-featuresand--by-componentssplit every block by feature or component, with the owners and tags of each part.- When nothing matches, it says how many tests were scanned and which filters ruled them out.
Test Junkie 0.9a6 · Python 3.12.5 · Windows 11
  tests    tests · 1 suite, 2 tests · found in 0.00s
  audit    owners
  filters  no owner

no owner                            2 tests · 100%  [||||||||||||||||]
  suites       ReportsSuite 2
  features     Analytics 2
  components   reports 1 · none 1
  tags         none 2
  tests        ReportsSuite.lists_reports · ReportsSuite.export_csv

Gaps 2 ─────────────────────────────────────────────────────────────────────────

  1 test   has  no component     tj audit owners --no-components
  2 tests  have no tags          tj audit owners --no-tags

────────────────────────────────────────────────────────────────────────────────

2 tests · 1 suite · 1 feature · 0 owners · 1 component · 0 tags
Test Junkie 0.9a6 · Python 3.12.5 · Windows 11
  tests    tests · 5 suites, 13 tests · found in 0.00s
  audit    components · by features

auth                                4 tests ·  31%  [|||||···········]
  suites       LoginSuite 4
  owners       qa-team 4
  tags         regression 2 · smoke 2
  feature      Accounts 4
               owners qa-team 4   tags regression 2 · smoke 2

payment                             4 tests ·  31%  [|||||···········]
  suites       CheckoutSuite 3 · PaymentsSuite 1
  owners       checkout-team 4
  tags         regression 3 · smoke 1
  feature      Billing 4
…
In CI: --json and --fail-on-gaps since 0.9a6
--json prints the view as JSON for scripts. --fail-on-gaps exits with code 1 when tests are missing metadata: owners, features, components or tags, or the kinds you list. Tag filters are the ones tj run uses: -k for any of the tags, -l for all of them.
# fail the build when a test has no owner or no tags
tj audit suites --fail-on-gaps owners,tags

# owners as JSON
tj audit owners --json
…
13 tests · 5 suites · 4 features · 3 owners · 5 components · 2 tags
 FAILED   2 tests without owner, 3 tests without tags  exit code 1
tj config since 0.8a.8
Saves settings for tj run and tj audit, so you don't type them every time. Three sub-commands: show, update and restore. Every option of tj run can be saved.
# Every setting, grouped, and where the config file is
tj config show --all

# Save sources and test threads once instead of repeating them on every run
tj config update -s /path/to/tests -T 4

# Clear individual settings, or all of them
tj config restore -s -T
tj config restore --all
Saved values can always be overridden at runtime — e.g. tj run --sources /path/to/suite.py takes precedence over whatever is in config.
What it prints since 0.9a6
update shows each setting's old and new value, and the exact command that undoes the change:
 SAVED   3 settings · C:\Users\you\AppData\Local\Test-Junkie\Test-Junkie\.tj.cfg
  test_multithreading_limit     ·  →  4
  run_on_match_any              ·  →  smoke
  sources                       ·  →  tests

  Undo: tj config restore -T -k -s
show --all groups the settings by what they control. Saved values are bold; unset ones are a dot, with the default when there is one. show -s -T prints just those settings.
Config  C:\Users\you\AppData\Local\Test-Junkie\Test-Junkie\.tj.cfg

Discovery
  sources                       tests
  guess_root                    ·  default off

Parallel and retries
  test_multithreading_limit     4
  suite_multithreading_limit    ·  default 1
  retry                         ·
  no_retry                      ·  default off
  retry_policy                  ·

Limits
  suite_throttling              ·  default 0
  test_throttling               ·  default 0
  ramp_up                       ·  default 0
  traceback_limit               ·  default 3000
  message_limit                 ·  default 3000
  truncate                      ·  default middle

Filters
  tests                         ·
  features                      ·
  components                    ·
  owners                        ·
  run_on_match_any              smoke
  run_on_match_all              ·
  skip_on_match_any             ·
  skip_on_match_all             ·

Reports and output
  html_report                   ·
  xml_report                    ·
  json_report                   ·
  monitor_resources             ·  default off
  code_cov                      ·  default off
  cov_rcfile                    ·
  quiet                         ·  default off
  per_test                      ·  default off
  no_capture                    ·  default off
  flag_flaky                    ·  default off
  fail_on_flaky                 ·  default off

────────────────────────────────────────────────────────────────────────────────

3 of 32 settings saved · tj config update -h to change one, tj config restore -h to clear one
 RESTORED   1 setting to its default
  test_multithreading_limit     4  →  default 1
A wrong value is rejected before anything is saved:
 ERROR   -T / --test-multithreading-limit needs a whole number, got "four".
         Nothing was saved. tj config update -h lists every option.
Project config since 0.9a6
Keep a project's settings with the project: save them to a tj.cfg in its root, and commit it. tj run, tj audit and tj config look for one from the current folder up and use it instead of your user config. Without -s and tj run picks up the saved sources, and if a suite's imports fail it retries with the project folder on the import path.
# create the project config
tj config update -s tests -T 4 --config ./tj.cfg

# from anywhere in the project
tj run

# which config is in use
tj version
A [tool.test_junkie] table in pyproject.toml works too (Python 3.11+, or with tomli installed). Test Junkie only reads it: change it in the file.
[tool.test_junkie]
sources = ["tests"]
test-multithreading-limit = 4
Where config is stored since 0.9a3
By default Test Junkie keeps its config (and resource-monitoring temp files) in your per-user app data directory — tj config show --all prints the exact path. Set the TEST_JUNKIE_HOME environment variable to use a different directory instead — useful in CI, containers, or anywhere you want runs isolated from a shared config.
# Use a throwaway config dir for this shell
export TEST_JUNKIE_HOME=/tmp/tj_home
tj config show --all
@Suite since 0.8a.8
Test Junkie is suite-based: every test must be defined inside a class, and that class must be
decorated with @Suite()
— see Basic Usage for a minimal example. This decorator
accepts a number of properties that let you control how the suite executes.
from test_junkie.decorators import Suite

@Suite()
class ExampleTestSuite:
    ...
| property | usage example |
|---|---|
| meta | @Suite(meta=meta(name="Suite Name", known_bugs=[11111, 22222, 33333])) |
| retry | @Suite(retry=2) |
| retry_policy | @Suite(retry_policy=Flaky) |
| uses | @Suite(uses="grid") |
| throttling | @Suite(throttling=0.5) |
| ids | @Suite(parameters=[eu, us], ids=["eu", "us"]) |
| skip | @Suite(skip=True) |
| listener | @Suite(listener=YourListenerClass) |
| rules | @Suite(rules=YourRulesClass) |
| parameters | @Suite(parameters=[{"user": "joe@example.com", "pass": "example"}, {...}, {...}]) |
| conflicts_with | @Suite(conflicts_with=[OtherSuite, "Suite.test"]) (was pr) |
| parallelized | @Suite(parallelized=False) |
| priority | @Suite(priority=1) |
| order | @Suite(order=TestOrder.RANDOM) |
| feature | @Suite(feature="Demo") |
| owner | @Suite(owner="John Doe") |
@beforeClass since 0.8a.8
Use this decorator to run a function once, before any tests in a @Suite() start. In a parameterized suite it runs once per suite parameter, before that pass's tests.
If an exception is raised inside the decorated function, it triggers the on_ignore event for every test in that suite, and none of them run.
from test_junkie.decorators import beforeClass

...
@beforeClass()
def before_class(self):
    ...
This decorator doesn't accept any properties of its own. In a parameterized suite, add a
suite_parameter
argument to receive the value for the current pass. Leaving it out doesn't stop the function from running
on every pass; it just isn't told which one. See
which functions run per suite parameter.
@beforeTest since 0.8a.8
This decorator runs a function immediately before every @test() case in the @Suite().
If it raises an exception, it triggers either the on_failure or on_error event for the test in scope.
from test_junkie.decorators import beforeTest

...
@beforeTest()
def before_test(self):
    ...
This decorator doesn't accept any properties of its own. The function it decorates can take
two optional arguments, in any order:
suite_parameter,
the current pass's value in a parameterized suite (None around a
test that runs once), and
test,
described below.
The test argument new since 0.9a8
Add test to the signature of a @beforeTest() or
@afterTest() function and it receives the test it runs around: the
same getters as a TestObject, so the hook can set up only what that
test needs.
- Name a trace, log or screenshot after the test that produced it.
- Log in only when the test runs per suite parameter
(
test.accepts_suite_parameters()). A guest flow leavessuite_parameterout, runs once, and its hooks getNone. - Read the test's meta, owner or component to label what the hook logs.
Hooks that don't declare test are called exactly as before.
@beforeClass() and @afterClass() never get it, since they don't run
around a single test.
@Suite()
class CheckoutSuite:

    @beforeTest()
    def start_trace(self, test):
        # one trace per test, named after it
        self.trace = tracing.start(
            name=test.get_function_name())

    @afterTest()
    def save_trace(self, test):
        name = test.get_function_name()
        self.trace.save("traces/" + name + ".zip")

    @test()
    def pays_with_card(self):
        ...
It's read-only, by design
Test Junkie keeps using the test after your hook returns: its tags, parameters, retry state and
meta decide what runs next, what's retried and what the reports say. So test is a
read-only view, not the live object. Nothing a hook does through it can change the run, even when
many tests run in parallel.
| In the hook you… | What happens |
|---|---|
call a getter: get_*(), is_*(), accepts_*(), skip_*(), parallelized_parameters() | You get a copy taken at that moment. Changing what comes back (test.get_tags().append("x")) changes only your copy. |
read test.suite | A read-only view of the SuiteObject, with the same rules. |
call get_function_object(), test.suite.get_class_object() or get_class_instance() | You get the real function, class or instance, uncopied. Class attributes stay the way to share state between hooks and tests. |
call get_parameters() | The test's parameters as declared. A parameter function is never called from a hook: process_functions is ignored. |
assign an attribute (test.started = time.time()) | It's kept on the view for that hook call only. The test never sees it. |
| call anything else, e.g. a method that changes state | AttributeError: '…' is not available on TestView: hooks get a read-only view…. Like any exception in the hook, it fails the test in scope (on_failure / on_error); the run itself carries on. |
isinstance(test, TestObject) is True. To record something about a run (an account id, a link), call
Meta.update() from the test itself; the hook's view is for reading.
Rules before_test()/after_test() get the same view in
kwargs["test"].
An individual test can opt out of running its suite's @beforeTest()
— see skip special functions on the @test() page.
@test since 0.8a.8
This decorator marks a function as a test case — all tests must be defined inside a class, see Basic Usage for a minimal example.
If the function raises an exception, it triggers either the on_failure or on_error event. If it succeeds, on_success fires.
from test_junkie.decorators import test

...
@test()
def example_test(self):
    ...
This decorator accepts many properties that let you control how each test executes.
| property | usage example |
|---|---|
| meta | @test(meta=meta(name="Suite Name", known_bugs=[11111, 22222, 33333])) |
| retry | @test(retry=2), or a retry policy: @test(retry=Flaky) |
| retry_on | @test(retry_on=[AssertionError]) |
| no_retry_on | @test(no_retry_on=[TimeoutError]) |
| skip | @test(skip=True) |
| skip_before_test | @test(skip_before_test=True) |
| skip_before_test_rule | @test(skip_before_test_rule=True) |
| skip_after_test | @test(skip_after_test=True) |
| skip_after_test_rule | @test(skip_after_test_rule=True) |
| parameters | @test(parameters=[{"user": "joe@example.com", "pass": "example"}, {...}, {...}]) |
| parallelized_parameters | @test(parallelized_parameters=True) |
| ids | @test(parameters=[alice, bob], ids=["alice", "bob"]) |
| uses | @test(uses="grid") |
| conflicts_with | @test(conflicts_with=[OtherSuite.other_test, "Suite"]) (was pr) |
| parallelized | @test(parallelized=False) |
| priority | @test(priority=1) |
| tags | @test(tags=["critical", "pre-deploy", "post-deploy"]) |
| component | @test(component="Authentication") |
| owner | @test(owner="John Doe") |
@afterTest since 0.8a.8
This decorator runs a function immediately after each @test() case finishes.
If it raises an exception, it triggers either the on_failure or on_error event.
@afterTest()
still runs even if @test()
raised an exception. If both raise, your listener gets both tracebacks and
exception objects, but the console output only shows the @test()
traceback.
from test_junkie.decorators import afterTest

...
@afterTest()
def after_test(self):
    ...
The test argument new
This decorator doesn't accept any properties of its own. The function it decorates can take
two optional arguments, the same as @beforeTest():
suite_parameter
(None after a test that runs once) and
test,
a read-only view of the test that just ran. See the test argument.
@afterTest()
def save_trace(self, test):
    # saved under the name of the test that just ran
    self.trace.save(
        "traces/" + test.get_function_name() + ".zip")
An individual test can opt out of running its suite's @afterTest()
— see skip special functions on the @test() page.
@afterClass since 0.8a.8
This decorator runs a function once, after every test in the suite has finished. If the suite
uses retry or parameters, @afterClass()
runs again for each retry/suite parameter.
If it raises an exception, it has no effect on test statuses and doesn't show up in the console output — but depending on the exception, either the on_after_class_fail or on_after_class_error event fires, so you can still capture it if needed.
It also runs when the run is cancelled: by Ctrl+C, Runner.cancel() or a hook raising KeyboardInterrupt.
from test_junkie.decorators import afterClass

...
@afterClass()
def after_class(self):
    ...
This decorator doesn't accept any properties of its own. Add a
suite_parameter
argument to receive the value for the pass that just finished. It runs on every pass either way. See
which functions run per suite parameter.
@GroupRules since 0.8a.8
This decorator defines rules that span a set of test suites, and it must decorate a method on a subclass of Rules.
Inside a method decorated with @GroupRules(),
import the suites you care about and wrap nested functions with @beforeGroup() and
@afterGroup() to build the actual rules. Define as many as you like — see the
Rules section for a fuller example.
@beforeGroup
Runs as soon as any suite in the group is about to start. If it raises an exception, every suite in the group is ignored and none of them are retried.
Parallel suites and several hooks new since 0.9a8
It runs once, even when the group's suites run in parallel: the first suite to start runs it, and the others wait for it to finish before running any tests. If it fails, they all get the same result.
Several @beforeGroup() functions for the same suites run in the order
they're defined. If one fails, the rest are skipped and the group is ignored. A suite that's
skipped or filtered out never starts the group, and its
parameters function isn't called.
from test_junkie.decorators import GroupRules, beforeGroup
from test_junkie.rules import Rules

class ExampleRules(Rules):

    @GroupRules()
    def group_rules(self):

        from ... import ExampleSuite1, ExampleSuite2

        @beforeGroup([ExampleSuite1, ExampleSuite2])
        def before_group_a():
            # your code
            pass
@afterGroup
Runs once every suite in the group has finished. This only applies to suites that were actually part of the Runner invocation — if you defined a rule for 20 suites but only run 1 of them, the rule still fires on completion of that 1 suite; the other 19 never run, so the condition is considered satisfied.
When it runs new since 0.9a8
It runs after the last suite of the group is done, however each one ended:
passed, failed, skipped, ignored or cancelled. That includes a run stopped with Ctrl+C, Runner.cancel() or a hook raising KeyboardInterrupt, and a
@beforeGroup() that failed, so cleanup still happens after a half-finished
setup.
It doesn't run if the group never started: no @beforeGroup() ran
(for example, every suite in the group was skipped). For a group without a
@beforeGroup(), it runs if at least one of its suites ran.
If it raises an exception, it has no effect on test statuses and doesn't show up in the console output — but either on_after_group_fail or on_after_group_error fires, so you can still capture it.
@afterGroup([ExampleSuite1, ExampleSuite2])
def after_group_a():
    # your code
    pass
Skip since 0.8a.8
Test Junkie supports skipping at both the test and suite level, via the skip
property on @test() or @Suite(), which accepts either a
boolean
or a function.
If the boolean (or the function's return value) is True,
the test or the whole suite is skipped, and the on_skip or
on_class_skip event fires accordingly.
skip only runs when it's actually needed, so you don't pay for irrelevant checks.meta argument, the test's metadata is passed in automatically.from test_junkie.decorators import Suite, test def custom_skip_function(meta): # meta is optional # do your processing return True # or False, must return a boolean @Suite(skip=True) # or skip=custom_skip_function class ExampleSuite: @test(skip=True) # or skip=custom_skip_function def example_test(self): pass
runtime skip since 0.9a2
You can skip a test from within the test body at run time using skip()
from test_junkie.shortcuts. Call it when you discover during
execution that the test no longer makes sense to run — an account isn't configured, a dependency
isn't available, a precondition isn't met — and you want to mark it as skipped rather than
failing or passing it.
This fires the same on_skip listener event and counts as a
skip in all reports, exactly like a static skip=True on the
decorator.
An optional reason string can be passed for
diagnostics.
retry is set on the suite.from test_junkie.decorators import Suite, test from test_junkie.shortcuts import skip @Suite() class CheckoutSuite: @test() def test_checkout_flow(self): if not account_has_payment_method(): skip("payment method not configured") # ... rest of the test
skip special functions
Sometimes a test needs to opt out of the lifecycle hooks that run around it — without removing those hooks from every other test in the suite. Four properties on @test() give you that control:
skip_before_test— don't run @beforeTest() for this testskip_after_test— don't run @afterTest() for this testskip_before_test_rule— don't run the suite's Rulesbefore_test()for this testskip_after_test_rule— don't run the suite's Rulesafter_test()for this test
All four are scoped to the single test they're declared on — every other test in the suite is unaffected.
...
@test(skip_before_test=True,
      skip_after_test=True,
      skip_before_test_rule=True,
      skip_after_test_rule=True)
def example_test(self):
    pass
Retry since 0.8a.8
Test Junkie can retry tests at both the test and suite level, generically or based on the specific exception raised.
Suite retries — once a suite's initial run finishes, if any tests are still unsuccessful and the suite's retry limit is higher than 1, Test Junkie re-runs the whole suite up to that limit or until every test passes, whichever comes first. On a suite retry, @beforeClass() and @afterClass() run again, and test-level retries apply again too.
Test retries — once a test's initial run finishes, if it was unsuccessful, it's retried immediately up to its retry limit or until it passes, whichever comes first.
from test_junkie.decorators import Suite, test

@Suite(retry=2)  # default is 1
class ExampleSuite:

    @test(retry=2)  # default is 1
    def example_test(self):
        # this test can run up to 4 times total:
        # suite_retry x test_retry = max total test retries
        assert True is False
retry on specific exception
...
@test(retry=2, retry_on=[AssertionError])
def example_test(self):
    # will be retried, since it failed with AssertionError
    assert True is False
...
no retry on specific exception
...
@test(retry=2, no_retry_on=[AssertionError])
def example_test(self):
    # won't be retried, this exception is explicitly excluded
    assert True is False
...
Both retry_on
and no_retry_on
take a list of exception classes — useful when you want to retry on a flaky, known-transient error
without masking every other kind of failure. If you're using retries on a parameterized
test, only the parameters that didn't pass get retried. To run only
what didn't pass again in a later run, see Rerun.
Subclasses count: retry_on=[requests.exceptions.Timeout] also retries a ReadTimeout. since 0.9a6
A test can use both lists; no_retry_on is checked first.
Flaky tests new since 0.9a8
A test is flaky when it passed only after failing or erroring in the same run. Test Junkie
tracks that for every test, whatever retried it: retry=N, a
retry policy or a suite retry pass. It's kept per parameter
combination, so a test can be flaky for admin and solid for viewer. A flaky test
still counts as passed; the flag is extra information, unless you ask for --fail-on-flaky.
test.is_flaky(parameter=None, suite_parameter=None)answers for one combination.test.get_flaky()lists every flaky combination with the run it passed on and the errors before that.- The JSON report gives every test
"flaky": trueorfalse; the XML report keeps each failed run as a<flakyFailure>CI tools read. tj run --flag-flakylists them after the summary and, with-p, labels themFLAKYinstead ofPASSED;--fail-on-flakyalso fails the run with exit code 1.
runner.run()
for suite in runner.get_executed_suites():
    for test in suite.get_test_objects():
        for flaky in test.get_flaky():
            print(test.get_function_name(),
                  flaky["suite_parameter"],
                  flaky["passed_on_run"],
                  flaky["errors"])

# or ask about one combination
test.is_flaky(suite_parameter="admin")
$ tj run -s tests --flag-flaky
...
Flaky 1 ────────────────────────────────────────────────────────────────────────

  CheckoutSuite.pays_with_card [suite: admin]  passed on run 2
      TimeoutError: payment page not loaded after 10s

 PASSED   exit code 0

$ tj run -s tests --fail-on-flaky
...  a Problems entry per flaky test and the same Flaky block, then:
 FAILED   1 flaky test (--fail-on-flaky)  exit code 1
Retry Policies new since 0.9a8
Different failures deserve different retries. A timeout may be worth three quick tries, a
503 two tries with a pause, and a permission error none at all. A
retry policy says that once, in a class you can share across tests and suites.
Each When(...) describes one kind of failure: exception classes
(subclasses count), text to find in the error, or both. When a run fails, the first matching
When decides whether to retry and how long to wait. Each one has its own budget of
attempts, so a test that times out once and then gets a 503 spends one try from each.
A failure no When matches isn't retried, and no_retry_on always wins.
Use it on a test with @test(retry=Flaky), change a field for one test
with retry=Flaky(attempts=2), or set it for a whole suite with
@Suite(retry_policy=Flaky). A test that sets its own retry keeps it.
passed on run 2 (Flaky, when "503": waited 20s). The failure details mark each retried run, the HTML report shows it on every attempt, the JSON report adds retry to each run, and listeners get on_retry before each retry.from test_junkie.retry import RetryPolicy, When class Flaky(RetryPolicy): no_retry_on = [PermissionError] # never retried when = [ When(TimeoutError, attempts=3, delay=1), When(message="503", attempts=2, delay=20, backoff=2), ] @Suite(retry_policy=Flaky) # tests without retry= class CheckoutSuite: @test() def pays_with_card(self): ... @test(retry=Flaky(attempts=2)) # at most 2 runs def refunds(self): ... @test(retry=1) # opt out def shows_receipt(self): ...
Here is Flaky on a real run. The timeout and the 503 each pass on their second
run, and the PermissionError is never retried, so it fails after one run:
$ tj run -s tests -p
...
CheckoutSuite  tests\checkout.py
  PASSED     pays_with_card   passed on run 2 (Flaky, when TimeoutError: waited 1s)   0.00s  [ 33%]
  PASSED     refunds          passed on run 2 (Flaky, when "503": waited 20s)         0.00s  [ 66%]
  ERROR      shows_receipt                                                             0.00s  [100%]
...
[ERROR] CheckoutSuite.shows_receipt
        tests\checkout.py:36 · 1 run · 0.00s
...
  │ PermissionError: receipt needs the billing role
| Field | Default | What it does |
|---|---|---|
attempts | 1, or one run plus each when's retries | Most runs in total, the first one included. Without when, the policy retries any failure up to this many runs. With when, each condition has its own budget, so a test gets one run plus every condition's retries (budgets of 3 and 2 make 4 runs); set attempts as well to cap that lower. There is always a limit: not even should_retry() can retry past it. |
retry_on | any | Exception classes worth retrying; others aren't retried. Only used without when: a When names its own classes. |
no_retry_on | none | Exception classes never retried. Checked first, always wins. |
message | any | Only used without when. Text to find anywhere in the error, case-sensitive: message="503". Pass re.compile(r"HTTP 5\d\d", re.I) for a pattern, or a list of either. Matched against the error as raised, even if the report shows it truncated. |
delay | 0 | Seconds to wait before a retry. |
backoff | 1 | Multiplies the delay after each retry: delay=1, backoff=2 waits 1s, 2s, 4s… |
max_delay | none | The longest any single wait gets from delay and backoff; jitter is added after it. |
jitter | 0 | Adds up to this many random seconds to each wait, so parallel tests don't retry in lockstep. |
chain | False | Also look at what caused the error. API clients and SDKs often wrap the real one: raise ApiError(...) from timeout. With chain=True, When(TimeoutError) matches that ApiError, and message and no_retry_on check each cause too. Use it when your errors are wrapped. It also follows an error raised inside an except block, so a bug in error handling could be retried like the timeout it was handling; that is why it is off by default. |
max_time | none | A time limit, in seconds, on how long one test keeps retrying, counted from the start of its first run. Before each retry, the policy checks whether the wait before it would end past the limit; if so, it stops retrying and the test keeps its failure. With max_time=60 and delay=20, a test that has been failing for 50 seconds isn't retried again. A retry that starts in time can still finish after the limit. Use it to keep a slow test with long waits from holding up the run. |
reset | none | "class" sets the class up again before retrying, see below. Can be set on a single When too. |
circuit | none | After this many tests with this policy class failed even after retrying, it stops retrying for the rest of the run. Counted per class, so Flaky(attempts=2) and Flaky share one count. Something bigger is broken, and retrying only makes the run longer. |
when | none | A list of When conditions, each with its own budget and wait. See Building a When. |
Mistakes surface when the class is defined, not halfway through a run: a negative delay or a
When without attempts, in a policy without attempts, raises BadParameters naming the field. A policy and
retry_on/no_retry_on on the same @test() is an error too;
put them on the policy.
Building a When
A When is one kind of failure and how to retry it. It matches a failed run by what was
raised:
- Exception classes, as positional arguments:
When(TimeoutError, ConnectionError)matches either one, subclasses included. - Text with
message=: found anywhere in the error, case-sensitive. Are.compile(...)pattern or a list of either works too; any one of them is enough. - Both: the error has to be one of the classes and contain one of the texts.
- Neither:
When(attempts=2)matches any failure, which makes it a catch-all.
The policy checks its when list in order and the first match decides,
so put specific conditions first and a catch-all last. A failure nothing matches isn't retried.
Each When counts only the failures it matched: attempts=3 allows
up to three runs that fail that way, so a timeout and a 503 never use up each other's tries. Its
backoff grows with its own failures too: delay=10, backoff=2 waits 10s,
then 20s.
import re
from test_junkie.retry import RetryPolicy, When


class Checkout(RetryPolicy):
    delay = 1  # every When that sets no delay
    when = [
        # either class, up to 3 runs
        When(TimeoutError, ConnectionError,
             attempts=3),

        # ApiError AND one of the texts
        When(ApiError,
             message=["503",
                      re.compile("rate limit", re.I)],
             attempts=2, delay=10, backoff=2,
             name="server busy"),

        # anything else: one more try
        When(attempts=2),
    ]
| Argument | What it does |
|---|---|
*exceptions | Exception classes to match, subclasses included. None given: any class. |
message | Text or a re.compile(...) pattern to find in the error, or a list of them. None given: any text. |
attempts | Most runs that fail this way, the first included. Needed here unless the policy sets attempts. |
delay, backoff, max_delay, jitter | The wait before each retry, as on the policy. |
reset | "class" sets the class up again before this condition's retries only, see a fresh setup. |
name | The label the console and reports show, instead of one built from the classes and texts: when "server busy". |
An argument a When leaves out comes from the policy, so set shared values like
delay once on the class. chain and no_retry_on are policy-wide and
apply to every When; no_retry_on is checked first and always wins.
Hooks and a fresh setup
should_retry(error, decision, test) has the last word: it gets the
error, what the policy decided (decision.retry, decision.when,
decision.delay) and a read-only view of the test,
and returns whether to retry. Returning True retries even a failure no
When matched.
before_retry(error, decision, test) runs after the wait,
right before the retry: refresh a token, clear a cache. If it raises, the test isn't retried and
keeps its failure; the reason shows where retries are reported.
reset="class" is for failures that leave the class's
state broken, like a logged-out session. The retry is held until that suite parameter's other
tests are done. Then @afterClass() and @beforeClass()
run once, and every held retry runs after that one fresh setup. If @beforeClass()
fails again, the held tests are ignored with its error.
class Session(RetryPolicy):
    when = [When(message="401", attempts=2),
            When(message="stale session",
                 attempts=2, reset="class")]
    max_time = 120

    def should_retry(self, error, decision, test):
        # never retry tests that move money
        tags = test.get_tags()
        return (decision.retry
                and "payments" not in tags)

    def before_retry(self, error, decision, test):
        tokens.refresh()  # runs right before the retry
For a whole run
A policy can cover a whole run: Runner.run(retry_policy=Flaky) or
tj run --retry-policy my_project.retries:Flaky.
It applies to every test that sets no retry of its own and whose suite sets no
retry_policy, for that run only.
Runner.cancel()) ends the wait straight away. tj run --no-retry switches policies off, and --retry N caps their runs.Rerun since 0.9a7
Retries happen inside a run. A rerun is a new run of only what didn't pass last time: the tests that failed, errored or were ignored, down to the parameter and suite parameter that didn't pass.
Save the results with --json-report, then give that report to
--rerun. A test that failed for one of ten parameters runs again with that one
parameter. A suite parameter with nothing left to run is skipped as a whole, including its
@beforeClass() and @afterClass(), and so is a
suite with nothing left to run.
# run everything and keep the results
tj run -s tests --json-report reports/

# run again only what didn't pass
tj run -s tests --rerun reports/report.json
Only what runs again is reported, so a rerun's report and summary show the tests you're looking at, not the ones that already passed. Keep the first report if you need the full picture, or write the rerun's report somewhere else. Retries still apply inside a rerun, and only to the parameters it runs. If nothing failed, nothing runs and the run passes.
From code
Runner.run() takes the path to a report, or a Rerun. Build one from a
report, choosing which results run again, or add the tests yourself:
from test_junkie.constants import TestCategory
from test_junkie.rerun import Rerun
from test_junkie.runner import Runner

runner = Runner([LoginSuite, CheckoutSuite])
runner.run(rerun="reports/report.json")

# only the failures, not the errors and ignored tests
runner.run(rerun=Rerun.from_report("reports/report.json", statuses=[TestCategory.FAIL]))

# or say what runs again: suite, test, parameter, suite parameter
runner.run(rerun=Rerun().add("LoginSuite", "login", parameter="admin", suite_parameter="staging"))
Your own matching
If your results live somewhere else, like a database, subclass Rerun:
add() the tests that run again and override includes() to decide which of
their parameters do. It gets the real parameter values, not their text.
class FailedInDatabase(Rerun):

    def __init__(self, failed):
        super().__init__()
        self.failed = failed  # {(suite, test): {(suite parameter, parameter), ...}}
        for suite, test in failed:
            self.add(suite, test)

    def includes(self, suite, test, parameter=None, suite_parameter=None):
        return (suite_parameter, parameter) in self.failed.get((suite, test), ())

runner.run(rerun=FailedInDatabase(load_failures()))
Parametrization since 0.8a.8
Test Junkie has one of the most flexible parametrization engines of any Python test runner — parametrization is supported at both the suite and test level.
Suite parametrization — pass a parameters
list to @Suite() and the suite runs once for each value: a pass per suite
parameter, each with its own @beforeClass() and
@afterClass().
Hooks (@beforeClass(), @beforeTest(),
@afterTest(), @afterClass()) run on every pass
whether they ask for the value or not. Adding
suite_parameter
to a hook's signature only hands it the current value.
Tests are different: a @test() runs once per suite parameter only
if its signature takes suite_parameter.
Without it, the test runs once for the whole suite. See
which functions run per suite parameter below.
@Suite(parameters=[1, 2])
class ExampleSuite:

    @beforeClass()
    def before_class(self, suite_parameter):
        print(suite_parameter)

    @beforeTest()
    def before_test(self, suite_parameter):
        print(suite_parameter)
Test parametrization — a test can use suite-level parameters, its own parameters, or both at
once. To give a test its own parameters, pass a parameters
list to @test() and add parameter
to the function's signature.
A test can run with neither, either, or both suite- and test-level parameters — whatever fits.
@Suite(parameters=[1, 2])
class ExampleSuite:

    @test(parameters=[10, 20])
    def example_test(self, parameter, suite_parameter):
        print(parameter)
        print(suite_parameter)
Which functions run per suite parameter
| Function | Runs | What suite_parameter in its signature does |
|---|---|---|
| @beforeClass() / @afterClass() | Once per suite parameter, always | Hands it the value for this pass. Leave it out and the hook still runs on every pass, it just isn't told which. |
| @test() | Once per suite parameter if it takes suite_parameter, otherwise once | Decides how many times the test runs. |
| @beforeTest() / @afterTest() | Around every test run | Hands it the value for that run. Around a test that runs once it's None. |
So you opt a test in or out of suite parameters with its signature; there's no flag for it. Which way to go depends on whether the test's outcome can change with the suite parameter:
Opt in (take suite_parameter) when the suite parameter is part of what you're
testing: the same checks for each user role, each locale, each environment, each API version. You
want a result per value, so a failure tells you which one broke.
Opt out (leave it out) when the test doesn't care which pass it's in: a health check, a schema check, something that only reads static data, or anything slow or costly you don't want repeated for every value. It runs once, on the first pass.
@beforeClass() and @beforeTest() run for that pass, so a @beforeTest() that reads suite_parameter gets None around it. Check test.accepts_suite_parameters() through the hook's test argument before you use the value.@test(retry=N) retries a failed test right away, in the same pass. With @Suite(retry=N), a test without suite_parameter that's still failing gets another try on the next suite parameter's pass, under that pass's @beforeClass().@Suite(parameters=["admin", "viewer"]) class AccountSuite: @beforeClass() def log_in(self, suite_parameter): self.session = login(suite_parameter) # opted in: runs for admin and for viewer @test() def sees_dashboard(self, suite_parameter): assert self.session.can_open("/dashboard") # opted out: runs once, the role doesn't matter @test() def api_is_up(self): assert ping("/health") == 200
Providers
For both @Suite() and @test(), the
parameters
property takes a list of any data type, or a function/method, which Test Junkie
calls when it's time to run the suite. Paired with parallel execution,
a function provider can save real time when generating parameters is itself slow.
def active_accounts():
    # called when the suite runs
    return db.accounts(active=True)

@Suite(parameters=active_accounts)
class AccountSuite:
    ...
Parameters that read the same new since 0.9a8
Each parameter needs its own text. Results, reports and
reruns find a parameter by str(parameter), so two parameters of one
test (or two suite parameters) that read the same, like 1 and "1", or objects
with the same __str__, are rejected: that test or suite is ignored with an error naming
them. For objects you can't change, name them with ids=, a list of text or a function of
the parameter, on @test() or @Suite(). A list needs one id
per parameter. ids= names objects only: text, numbers and None always use
their own text, so for 1 and "1" change the values themselves.
class Account:
    def __str__(self):
        return "Account"  # same for every account

@test(parameters=[alice, bob], ids=["alice", "bob"])
def logs_in(self, parameter):
    ...

# or work the names out
@test(parameters=load_accounts,
       ids=lambda account: account.login)
When a parameters function raises new since 0.9a8
If it raises, that suite or test is ignored with the traceback, and the rest of the run carries on; the run still fails at the end. A function that raised isn't called again in the same run, so suites sharing a provider that times out don't each wait for it.
Parallel Execution since 0.8a.8
A test suite that takes 40 minutes to run sequentially stops being something people actually run before
pushing. Test Junkie supports multi-threading out of the box, with nothing extra to install, and you allocate N threads as a pool for your suites
and/or tests. Thread allocation happens through the run() method of the
Runner instance, independently for suites
(suite_multithreading_limit) and tests
(test_multithreading_limit) — the same limits the CLI's -S
and -T flags set. See priority for how execution
order interacts with parallel scheduling.
Parallelized parameters
Parameterized tests can go a level deeper: each parameter of that test
can run concurrently too, not just the test itself. This only applies to test cases, not suites,
and it's off by default — set parallelized_parameters on
@test() to True to enable it. Useful when a
single test is parameterized across dozens of inputs and the parameters themselves are
independent (hitting different API endpoints, say) rather than sequential.
@test(parallelized_parameters=True, parameters=["a", "b", "c"])
def example_test(self, parameter):
    ...
Opting out of parallel mode
Some tests just aren't safe to run concurrently with anything else — a test that changes global
state, or hits hardware only one process can touch at a time. Set parallelized
to False on @Suite() or @test()
and it runs sequentially, after every parallelized suite/test has already finished.
A test that runs alone
@test(parallelized=False) runs alone in the whole
run: Test Junkie waits for what's running to finish, and nothing else starts, in any suite,
hooks included, until the test and all of its parameters are done.
That pauses everything else, so if you know which tests clash, use conflicts_with=
so only those wait. A test that runs alone can't also set
parallelized_parameters=True; that combination is rejected.
@Suite(parallelized=False)
class ExampleSuite:

    @test(parallelized=False)
    def example_test(self):
        ...
Conflicts new since 0.9a8
Two tests can each be perfectly parallel-safe on their own and still conflict with each other —
one logs a user out while the other assumes it's still logged in, for example. conflicts_with
on @test() or @Suite() tells Test Junkie which tests must
never run at the same time. Everything else keeps running in parallel.
- A target can be a test function, a suite class (all of its tests), or their names as text:
"Suite"or"Suite.test". Names avoid circular imports between suite files; objects are checked by your editor, so prefer them when you can. - On
@Suite()it applies to every test of the suite. A test may name a suite, and a suite may name a single test. - It works both ways: naming B on A also keeps B away from A.
- A test holds its place until its last parameter is done, so nothing it conflicts with starts between its parameters.
- Every target is checked when the run starts: a name that matches nothing, a target of the wrong
type or a test naming itself raises
BadParametersbefore any test runs.
# every test of both suites
@Suite(conflicts_with=[CheckoutSuite])
class InventorySuite:

    @test(conflicts_with=[
        "PricingSuite.updates_prices"])
    def recounts_stock(self):
        ...

    # a test can name a whole suite
    @test(conflicts_with=[ReportsSuite])
    def rebuilds_index(self):
        ...
pr= keeps working through 1.x as an alias of conflicts_with=, with a FutureWarning once per run; it goes no earlier than 2.0. Passing both on the same decorator is an error. get_parallel_restrictions() returns the targets either way.Many tests, one thing they all touch
Listing every pair gets long. Give the shared thing a resource pool of size 1 instead, and mark each test that uses it: they take turns, and the rest of the run carries on.
from test_junkie.objects import Limiter

Limiter.pool("inventory_db", max_concurrent=1)

@test(uses="inventory_db")
def recounts_stock(self): ...

@test(uses="inventory_db")
def imports_catalog(self): ...
Seeing it work
Two suites run side by side, and recounts_stock conflicts with
updates_prices. updates_prices waits until recounts_stock is done,
and the run below says so on its line.
The JSON report adds conflict_waits to each test that
waited: how long, and for which tests.
{
  "name": "updates_prices",
  "status": "success",
  "conflict_waits": [
    {
      "seconds": 2.001,
      "with": ["InventorySuite.recounts_stock"]
    }
  ],
  ...
}
@Suite()
class InventorySuite:

    @test()
    def lists_warehouses(self):
        time.sleep(0.3)

    @test(conflicts_with=[
        "PricingSuite.updates_prices"])
    def recounts_stock(self):
        time.sleep(2)


@Suite()
class PricingSuite:

    @test()
    def shows_discounts(self):
        time.sleep(0.3)

    @test()
    def updates_prices(self):
        time.sleep(0.5)
$ tj run -S 2 -T 2 -p

InventorySuite  shop_suites.py
  PASSED     lists_warehouses                                         0.30s  [ 25%]
  PASSED     recounts_stock                                           2.00s  [ 50%]

PricingSuite  shop_suites.py
  PASSED     shows_discounts                                          0.30s  [ 75%]
  PASSED     updates_prices    waited 2s (conflicts with InventorySuite.recounts_stock)   0.50s  [100%]
tj audit conflicts lists every pair of tests kept apart, without running anything.
--json prints it for scripts.
$ tj audit conflicts

  InventorySuite.recounts_stock  x  PricingSuite.updates_prices

$ tj audit conflicts --json
{
 "conflicts": [
  [
   "InventorySuite.recounts_stock",
   "PricingSuite.updates_prices"
  ]
 ]
}
Throttling & Resource Pools new since 0.9a8
Parallel execution is fast until it's too fast for something your tests share: a Selenium Grid with five browser slots, a sandbox API that allows two calls a second, a staging database that falls over at twenty connections. When that happens, tests fail with session timeouts and HTTP 429s that have nothing to do with your code. Test Junkie has five settings for this, from broad to targeted:
| Setting | What it limits | Set with |
|---|---|---|
| Thread limits | How many suites and tests run at the same time | -S / -T, run(suite_multithreading_limit=, test_multithreading_limit=) |
| Throttling | How often a new suite or test may start, across the whole run | Limiter.TEST_THROTTLING, --test-throttling, @Suite(throttling=) |
| Resource pools | How many tests use one resource at once, and how often they start | Limiter.pool(), @test(uses=), @Suite(uses=) |
| Ramp-up | How quickly the thread limits are reached | Limiter.RAMP_UP, --ramp-up |
| Conflicts | Which suites or tests must never run at the same time | @Suite(conflicts_with=), @test(conflicts_with=) |
Throttling
Throttling sets the time between starts. TEST_THROTTLING = 1 means
at most one new test per second across the whole run. That holds however many suites are
running in parallel. The first test starts right away. SUITE_THROTTLING
does the same for suites, which spreads out each suite's @beforeClass():
logins, browser launches, test data setup.
Throttling applies to parallel runs. A run with one thread starts its tests one after
another anyway. To pace those, use a resource pool with
min_interval.
from test_junkie.objects import Limiter

# the grid queues 12 sessions that arrive at once
# one new test per second, run-wide
Limiter.TEST_THROTTLING = 1
# one new suite (and its login) every 5 s
Limiter.SUITE_THROTTLING = 5

runner.run(suite_multithreading_limit=4,
           test_multithreading_limit=12)
A suite can set its own spacing with @Suite(throttling=). It replaces
TEST_THROTTLING for that suite's tests, so you can exempt fast suites
or slow down one fragile service. Every other suite keeps the run-wide value.
Limiter.TEST_THROTTLING = 1

# pure API checks: no spacing
@Suite(throttling=0)
class PricingApiSuite: ...

# legacy billing service: 3 s apart
@Suite(throttling=3)
class LegacyBillingSuite: ...
Resource pools
Throttling slows everything down. Usually only some tests touch the scarce resource: the UI tests need a grid slot, but the API tests don't. A resource pool caps just those tests, while the rest of the run uses every thread.
Define a pool with Limiter.pool(name, max_concurrent=None,
min_interval=0) and claim it with uses= on
@test(), or on @Suite() for every test in the suite.
max_concurrent caps how many tests hold the pool at once.
min_interval spaces out how often they start, which suits
rate-limited APIs.
from test_junkie.objects import Limiter

# 5 browser slots
Limiter.pool("grid", max_concurrent=5)
# sandbox API: 2 calls at once, 2 a second
Limiter.pool("payments", max_concurrent=2,
             min_interval=0.5)

# every test in the suite takes a grid slot
@Suite(uses="grid")
class CheckoutUiSuite: ...

@Suite()
class OrdersSuite:

    # a slot in both pools
    @test(uses=["grid", "payments"])
    def pay_by_card(self): ...

    # no pool: runs whenever a thread is free
    @test()
    def order_history_api(self): ...

runner.run(test_multithreading_limit=20)
- A test takes its slots right before @beforeTest() and gives them back after
@afterTest(), even if it fails. Each retry attempt takes
them again.
@beforeClass()and@afterClass()don't take slots. - A test waiting for a slot keeps its thread, so set
-Thigher than the pool. Then the other tests keep running while some wait. - Tests that use several pools take them in name order, so two tests can never each hold the pool the other is waiting for.
- A
uses=that names a pool you never defined fails the run before anything starts, with the name and the fix. - Pools work in single-threaded runs too:
min_intervalstill spaces the tests out. - Cancelling the run (Ctrl+C or runner.cancel()) cancels the tests still waiting for a slot.
Limiter.get_pools() shows each pool's
settings and how many tests hold it right now. Limiter.remove_pools() removes
them. Pools and conflicts solve different problems:
conflicts_with= keeps two named tests from running together, and a pool caps how many
tests run together.
Ramp-up
Limiter.RAMP_UP starts the run with one thread and grows the suite and
test thread limits evenly to -S and -T
over that many seconds. Use it when the system under test needs to warm up: a grid that
autoscales, cold caches, a freshly deployed service, or connection pools that open lazily.
# 1 thread, ~6 after 15 s, all 12 after 30 s
Limiter.RAMP_UP = 30
runner.run(test_multithreading_limit=12)
For one run, from the CLI, or saved
Every limit can also be set for a single run, with Runner.run() or
tj run, or saved with tj config update.
Precedence: run() and the command line first, then the saved
config, then what Limiter is set to in code. After the run,
Limiter goes back to what you set in code.
# CI against the shared grid
tj run -S 4 -T 12 --test-throttling 1 --ramp-up 30

# or save it for every tj run
tj config update --test-throttling 1 --ramp-up 30
runner.run(test_multithreading_limit=12,
           test_throttling=1, ramp_up=30)
| run() / config | tj run | Limiter |
|---|---|---|
suite_throttling | --suite-throttling S | SUITE_THROTTLING |
test_throttling | --test-throttling S | TEST_THROTTLING |
ramp_up | --ramp-up S | RAMP_UP |
traceback_limit | --traceback-limit N | TRACEBACK_LIMIT |
message_limit | --message-limit N | EXCEPTION_MESSAGE_LIMIT |
truncate | --truncate MODE | both *_TRUNCATE |
Limiter.ACTIVE = False switches off throttling, pools, ramp-up and truncation at once, e.g. for a local debugging session. Pools are defined in code: call Limiter.pool() at the top of a module your suites import, so tj run has them before the run starts.Rules since 0.8a.8
Suites often share setup/teardown logic that doesn't belong hardcoded into every
@beforeClass() — clearing a shared cache, resetting a feature flag, logging
timing for every test regardless of which suite it's in. Rules gives you a
reusable class for exactly that: write the logic once, then attach it to as many suites as you like via
@Suite(), instead of copy-pasting the same lifecycle code into every suite that needs
it. For logic that spans a group of suites rather than living inside one, see
@GroupRules below.
To create rules, subclass Rules and override whichever
lifecycle methods you need:
| method | runs alongside |
|---|---|
before_class(self) | @beforeClass() |
before_test(self, **kwargs) | @beforeTest() — kwargs.get("test") gives a read-only view of the current TestObject |
after_test(self, **kwargs) | @afterTest() — same kwargs.get("test") access |
after_class(self) | @afterClass() |
A suite's own @beforeClass()/@beforeTest()/etc. and its Rules class
both run — Rules doesn't replace them, it adds a second, reusable layer alongside.
from test_junkie.decorators import GroupRules, afterGroup, beforeGroup
from test_junkie.rules import Rules


class TestRules(Rules):

    def __init__(self, **kwargs):
        Rules.__init__(self, **kwargs)

    def before_class(self):
        # your code
        pass

    def before_test(self, **kwargs):
        # your code
        pass

    def after_test(self, **kwargs):
        # your code
        pass

    def after_class(self):
        # your code
        pass

    @GroupRules()
    def group_rules(self):

        from my.suites.examples import ExampleSuite1, ExampleSuite2

        @beforeGroup([ExampleSuite1, ExampleSuite2])
        def before_group_a():
            # your code
            pass

        @afterGroup([ExampleSuite1, ExampleSuite2])
        def after_group_a():
            # your code
            pass


@Suite(rules=TestRules)
class ExampleSuite:
    ...
Rules method runs per-suite, for every suite it's attached to. @GroupRules() marks a method on the same class as the place to declare @beforeGroup()/@afterGroup() hooks instead - those run once for a whole group of suites, not once per suite. See @GroupRules for the full reference.The test they get new since 0.9a8
before_test and after_test get kwargs["test"]: the same
read-only view a suite's own hooks get through their
test argument, including test.suite. Read the test's
name, tags, owner or meta to decide what the rule does.
Setting attributes on it changes only that rule's copy, never the run, so rules stay safe when tests run in parallel.
class LoggingRules(Rules):

    def before_test(self, **kwargs):
        test = kwargs["test"]
        log.info("start %s.%s (owner: %s)",
                 test.suite.get_class_name(),
                 test.get_function_name(),
                 test.get_owner())

    def after_test(self, **kwargs):
        test = kwargs["test"]
        log.info("done %s", test.get_function_name())


# one rule, every suite that attaches it
@Suite(rules=LoggingRules, owner="Payments team")
class CheckoutSuite:
    ...
Priority since 0.8a.8
When one test has to run before another — a login has to succeed before you can test account settings,
say — priority is how you say so. It influences execution order for
suites and tests. Influences, not guarantees: priority can't be
honored exactly in threaded mode once some suites have
parallelized set to False, or
parallel restrictions configured. Test Junkie always looks for a suite or
test it can run right now; if the next one in priority order is currently restricted and can't execute,
it moves on to something that can, rather than stalling the whole run waiting for one slot to clear.
That's a deliberate throughput trade-off, not a bug — if you need strict ordering, pair
priority with parallel restrictions or turn
off parallel execution for the suites/tests involved.
Priority is integer-based, starting at 1 (the highest priority) and increasing from
there. Set it via the priority property of @Suite() or
@test():
from test_junkie.decorators import Suite, test

@Suite()
class AccountSuite:

    @test(priority=1)
    def test_login(self):
        # runs before test_update_profile below
        ...

    @test(priority=2)
    def test_update_profile(self):
        ...
| configuration | ordering |
|---|---|
Explicit priority set | Runs in ascending priority order, always ahead of unprioritized tests |
No priority, parallel execution enabled | De-prioritized less — Test Junkie has more room to schedule it opportunistically |
No priority, parallel execution disabled | De-prioritized most — runs after all prioritized and unprioritized parallel tests |
Order since 0.9a2
The order argument on @Suite() controls how
tests within that suite are sequenced. It accepts a TestOrder constant and
overrides the default priority-ascending sort for that suite entirely — including any numeric
priority values set on individual tests.
from test_junkie.decorators import Suite, test
from test_junkie.constants import TestOrder

@Suite(order=TestOrder.ALPHABETICAL)
class LoginSuite:

    @test()
    def test_login_valid_credentials(self): ...

    @test()
    def test_login_expired_password(self): ...

    @test()
    def test_login_invalid_credentials(self): ...
| TestOrder constant | behaviour |
|---|---|
TestOrder.PRIORITY_ASC |
Numeric priority ascending (1 first). Tests with no priority run after. This is the default when order is not set. |
TestOrder.PRIORITY_DESC |
Numeric priority descending (highest number first). Tests with no priority still run last. |
TestOrder.ALPHABETICAL |
Tests sorted by function name A → Z. Numeric priority values are ignored. |
TestOrder.RANDOM |
Tests shuffled on every Runner instantiation. Useful for surfacing hidden order dependencies between tests. Numeric priority values are ignored. |
Listeners since 0.8a.8
Test Junkie fires 22 named events as a run progresses - a test starting, passing, retrying, a suite's
@beforeClass() blowing up, and so on. Defining a listener is optional,
but it's the seam you'd use for anything that isn't "run the tests": pushing metrics somewhere,
posting to Slack on failure, collecting artifacts, or driving your own dashboard off live run state.
To create a listener, subclass Listener and override whichever
events you care about - every overridden method must accept **kwargs.
Attach it to a suite via @Suite(), the same way Rules
attach.
See meta for reading/updating test metadata from inside a
listener, and SuiteObject / TestObject for
everything you can pull out of kwargs.
from test_junkie.listener import Listener

class MyTestListener(Listener):

    def __init__(self, **kwargs):
        Listener.__init__(self, **kwargs)

    def on_failure(self, **kwargs):
        properties = kwargs["properties"]
        test = properties["jm"]["jto"]
        exc = kwargs.get("exception")
        notify_slack(f"{test.get_function_name()} failed: {exc}")
exception/trace - only for events triggered by an exception), the SuiteObject (all events), and the TestObject (test-related events only).If a listener raises new since 0.9a8
A bug in a listener doesn't change any test results, and it doesn't stop the run. The exception is
recorded, and the suite carries on with its remaining tests. Each failed call is listed under Problems as a
LISTENER entry, with the event, the test's parameters and the traceback.
The run still fails: once every suite is done, Runner.run() raises
TestListenerError and the console verdict reads, for example,
FAILED 2 listener calls failed.
Test events
| Event | Fires when |
|---|---|
on_in_progress | Test Junkie starts processing the @test(). Fires once per parameter for parameterized tests. |
on_success | @beforeTest(), @test(), and @afterTest() (whichever apply) all ran without an exception. |
on_failure | Any of those three raised an unhandled AssertionError. |
on_error | Any of those three raised an unhandled exception other than AssertionError. |
on_ignore | A @beforeClass() raised, or bad input was passed to a @test() property. Also fires for every test a suite never got to because it ended early, e.g. a test called sys.exit(). |
on_cancel | Test execution was canceled - fires for every remaining test in the suite, including every test of a suite the cancel came before. |
on_skip | The test was skipped via @test() or regression filtering by feature/component/tag/assignee. |
on_retry | A test is about to run again after a failure. properties["retry"] has run (the run that failed), policy and when (what matched; None for plain retry=N) and waited (seconds it will wait first). Fires before the wait. |
on_complete | The test is done, regardless of outcome. Fires once per parameter. |
Suite & group events
| Event | Fires when |
|---|---|
on_class_in_progress | Test Junkie starts processing the @Suite(). |
on_before_class_failure | @beforeClass() raised AssertionError. Also fires on_ignore for every test in scope. |
on_before_class_error | @beforeClass() raised any other exception. Also fires on_ignore for every test in scope. |
on_after_class_failure | @afterClass() raised AssertionError. |
on_after_class_error | @afterClass() raised any other exception. |
on_class_skip | The suite was skipped via @Suite() or regression filtering. |
on_class_cancel | Execution was canceled - fires for every suite still queued (not yet in progress). A KeyboardInterrupt from a hook or listener cancels the same way. |
on_class_ignore | Test Junkie detected bad arguments on @Suite() - e.g. an empty parameters list that setup/tests depend on, so the suite can't meaningfully run. |
on_class_complete | The suite finished entirely, including retries and all suite-level parameters. Doesn't fire if the suite was skipped or canceled. A suite with a cancelled test reports as cancelled. |
on_before_group_failure | @beforeGroup() raised AssertionError. |
on_before_group_error | @beforeGroup() raised any other exception. |
on_after_group_failure | @afterGroup() raised AssertionError. |
on_after_group_error | @afterGroup() raised any other exception. |
Meta since 0.8a.8
Meta has no effect on how Test Junkie runs tests and can hold any data type. It's supported by both the @Suite() and @test() decorators.
Why is this useful? You can use meta to attach:
- Test name, suite name, description, expected results, or anything else useful in reports
- Test case IDs - if you have a test management system, link test scripts directly to test cases and build further integrations from there
- Bug ticket IDs - if you have a bug tracker (like Jira), link known failures to real tickets and process them differently (e.g. as a known failure rather than a fresh regression)
Test Junkie can do a lot for reporting out of the box, but no off-the-shelf tool beats a custom report built in-house by someone who knows the product. Meta exists to feed useful data into whatever reporting you build.
from test_junkie.decorators import Suite, test
from test_junkie.meta import meta


@Suite(listener=MyTestListener, meta=meta(name="some value", id=123))
class ExampleSuite:

    @test(meta=meta(name="some value", expected="some value",
                    known_bugs=[111, 222, 333], id=321))
    def example_test(self):
        pass
Setting meta while a test runs new since 0.9a8
Meta.update(**values) adds or changes metadata of the running test: the
order it created, the response it got, a link to its log. You don't pass self or the
parameters. Each thread that runs a test knows which test, parameter, suite parameter and attempt
it is running, so the values land on the right one, even from a helper three calls deep.
Meta.get(key) reads a value back, declared or set, and
Meta.get() gives a copy of all of them. Values can be anything; listeners get them
as they are. The declared @test(meta=...) is never changed: updates live with the
results, per parameter.
Where you can call it
- The test, or any helper it calls:
Meta.update()writes to the running test, for its current parameter and suite parameter. - @beforeTest(), @afterTest(), Rules before_test / after_test: the same, for the test the hook runs for.
- A thread the test starts: wrap its function with
Meta.bind(fn)first. - @beforeClass(), @afterClass():
no test is running yet, so use
Meta.suite.update(); a plainMeta.update()raises there. - Anywhere else (import time, a thread without
bind): raisesTestJunkieUsageErrorsaying how to fix it.
from test_junkie.decorators import (
    Suite, test, beforeClass, afterTest)
from test_junkie.meta import Meta, meta


def place_order(account):
    order = api.post("/orders", account=account)
    # a helper: no self, no parameters
    Meta.update(order_id=order.id)
    return order


@Suite(parameters=["admin"], listener=Recorder,
       meta=meta(team="payments"))
class CheckoutApiSuite:

    @beforeClass()
    def login(self, suite_parameter):
        session = api.login(suite_parameter)
        Meta.suite.update(session=session)

    @afterTest()
    def evidence(self):
        Meta.update(log=api.save_log())

    @test(retry=2, meta=meta(
        name="Checkout", expected="order is created"))
    def checkout(self, suite_parameter):
        order = place_order(suite_parameter)
        Meta.update(status=order.status)
        assert Meta.get("status") == 201
Threads you start new since 0.9a8
The running test is known per thread, so a thread your test starts doesn't know it. Wrap the
thread's function with Meta.bind(fn) before starting it: inside,
Meta.update() and Meta.get() work as they do in the test.
Call bind in the test, before the thread starts. Without it,
Meta.update() in the thread raises TestJunkieUsageError instead of
guessing which test you meant.
import threading
from test_junkie.meta import Meta


@test()
def bulk_import(self):
    def worker(batch):
        Meta.update(**{batch: "imported"})

    thread = threading.Thread(target=Meta.bind(worker),
                              args=("batch_a",))
    thread.start()
    thread.join()
    assert Meta.get("batch_a") == "imported"
Suite meta from class hooks new since 0.9a8
Meta.suite.update(**values) sets suite-level values, once per suite
parameter: a session id from @beforeClass(), a cleanup count from
@afterClass(). Listeners get them merged into
properties["suite_meta"], after the declared @Suite(meta=...), which stays
unchanged too. Meta.suite.get(key) reads them back. It works in per-test hooks and tests
as well, and always writes to the current suite parameter.
Lists, links and attachments new since 0.9a8
Three calls add to a list on the running test instead of replacing a value. They work in the same
places as Meta.update().
Meta.append(key, value)addsvalueto the list underkey, created on first use: one line per step, say. If the key already holds something that isn't a list, it raisesTestJunkieUsageError.Meta.link(label, url)adds{"label", "url"}to"links". The same label and URL again, on a retry for example, is listed once.Meta.attach(name, content, mime=None)adds a file to"attachments".contentis bytes, or the path of an existing file (encode text first). The file is copied right away, so later changes to it don't matter. Each entry is{"name", "size", "mime", "path", "source"}:pathis the saved copy,sourcethe path you passed (Nonefor bytes), andmimeis guessed from the name when you don't give one.
On a retry the lists keep growing, and each attempt in
get_meta_attempts() lists only what that attempt added. Listeners get them in
properties["test_meta"] like any other value.
The HTML report shows links as links and attachments as
downloads, with images previewed. Files up to 512 KB are embedded, so the report stays one file;
bigger ones are copied into a <report name>_files/ folder next to it
(report_files/ for report.html). The
JSON report has them under meta and each run's
meta_set.
from test_junkie.decorators import Suite, test
from test_junkie.meta import Meta

JIRA = "https://jira.example.com/browse/"


@Suite()
class CheckoutSuite:

    @test(retry=2)
    def pays_with_card(self):
        Meta.append("steps", "opened the cart")
        Meta.link("Jira", JIRA + "SHOP-482")
        Meta.attach("cart.png",
                    driver.get_screenshot_as_png())
        Meta.attach("app.log", "logs/app.log")
        checkout.pay_with_card()
        Meta.append("steps", "paid with card")
# run 1 failed after both steps, run 2 passed
test.get_meta()["steps"]
["opened the cart", "paid with card",
 "opened the cart", "paid with card"]
test.get_meta()["links"]
[{"label": "Jira",
  "url": "https://jira.example.com/browse/SHOP-482"}]
[a["name"] for a in
 test.get_meta()["attachments"]]
["cart.png", "app.log", "cart.png", "app.log"]
[a["attempt"] for a in
 test.get_meta_attempts(None, None)]
[1, 2]  # each: 2 steps, 1 link, 2 files
Retries: the merged view and each attempt new since 0.9a8
When a test is retried, its values carry forward: a key set in the
first run is still there after the second, unless the second sets it again.
test.get_meta(parameter, suite_parameter) gives that merged view.
test.get_meta_attempts(parameter, suite_parameter) shows what each run set, oldest first, so
you can tell which order belongs to the failed run. Each run keeps the latest value per key, not
every write, so a test that updates one key a thousand times stores one value. Runs that set nothing
aren't listed.
From the example above, in a real run: the first run timed out after creating order A-1001, and the retry created A-1002.
test.get_meta(None, "admin")
{"name": "Checkout", "expected": "order is created", "order_id": "A-1002",
 "log": "logs/checkout.txt", "status": 201}

test.get_meta_attempts(None, "admin")
[{"attempt": 1, "meta_set": {"order_id": "A-1001", "log": "logs/checkout.txt"}},
 {"attempt": 2, "meta_set": {"order_id": "A-1002", "status": 201, "log": "logs/checkout.txt"}}]
Reading meta in listeners new since 0.9a8
Every listener event gets three meta keys in properties:
test_meta: the test's merged values, plus"parameter"(the test parameter).suite_meta: the declared suite meta plusMeta.suite.update()values, plus"parameter"(the suite parameter).meta_attempts: what each run set, the same list asget_meta_attempts();Nonefor suite events.
They're copies: changing them doesn't change the test.
from test_junkie.listener import Listener


class Recorder(Listener):

    def on_complete(self, **kwargs):
        properties = kwargs["properties"]
        # merged values + "parameter"
        test_meta = properties["test_meta"]
        # what each run set
        attempts = properties["meta_attempts"]
        results_db.save(test_meta["name"],
                        test_meta.get("order_id"),
                        attempts)
properties["test_meta"]
{"name": "Checkout", "expected": "order is created", "order_id": "A-1002",
 "log": "logs/checkout.txt", "status": 201, "parameter": None}

properties["suite_meta"]
{"team": "payments", "session": "sess-42", "parameter": "admin"}

properties["meta_attempts"]
[{"attempt": 1, "meta_set": {"order_id": "A-1001", "log": "logs/checkout.txt"}},
 {"attempt": 2, "meta_set": {"order_id": "A-1002", "status": 201, "log": "logs/checkout.txt"}}]
Which values an event sees depends on when it fires:
| Event | Sees values set in |
|---|---|
on_in_progress | Earlier runs only: it fires before @beforeTest |
on_failure, on_error | @beforeTest and the test, not @afterTest: they fire when the test raises, before @afterTest runs |
on_success, on_complete | Everything, @afterTest included |
A listener that saves evidence from @afterTest (logs, screenshots) should do it
in on_complete, which runs once at the end with every value.
Meta in reports new since 0.9a8
- JSON report:
metaon every test (the merged values) andmeta_seton every run. - HTML report: a Metadata panel for each test variant, with keys set while running marked with the attempt that set them, and each attempt's own values under it.
- XML report: JUnit
<properties>on each test case, whose name includes its parameters.
Reports need text, so values are converted: bytes are decoded (bad bytes replaced), other
objects become their str(), and values longer than 2,000 characters (500 in the HTML report)
are cut with a note. Listeners still get the original objects. --rerun ignores the
meta fields.
{
 "name": "checkout",
 "suite_parameter": "admin",
 "meta": {"name": "Checkout", "expected": "order is created", "order_id": "A-1002",
          "log": "logs/checkout.txt", "status": 201},
 "runs": [
  {"status": "error", "meta_set": {"order_id": "A-1001", "log": "logs/checkout.txt"}, ...},
  {"status": "success", "meta_set": {"order_id": "A-1002", "status": 201, "log": "logs/checkout.txt"}, ...}
 ]
}
<testcase name="checkout[suite: admin]" classname="CheckoutApiSuite" status="success" time="0.000">
  <properties>
    <property name="name" value="Checkout"/>
    <property name="expected" value="order is created"/>
    <property name="order_id" value="A-1002"/>
    <property name="log" value="logs/checkout.txt"/>
    <property name="status" value="201"/>
  </properties>
  <flakyError type="TimeoutError" message="checkout API took 30s">...</flakyError>
</testcase>
The old call: Meta.update(self, ...) since 0.9a8
Meta.update(self, parameter=..., suite_parameter=..., **values) keeps working. It
writes to exactly the parameter and suite parameter you pass, missing ones included, and never
fills them in from the running test, so existing results don't move.
It warns with TestJunkieMetaWarning, once per line of code, when that's
probably a mistake:
- it wrote to a different slot than the one the test runs as, like the example, where the suite parameter wasn't passed;
- it found no running test (called at import time, or with the class instead of
self), so the values were dropped.
The run carries on either way. The usual fix is to drop self and the
parameters: Meta.update(name=...). Meta.get_meta("key") reads one key
and returns None outside a test.
@Suite(parameters=["admin"])
class LegacySuite:

    @test()
    def legacy(self, suite_parameter):
        # suite_parameter not passed
        Meta.update(self, name="Legacy")
TestJunkieMetaWarning: Meta.update(self, ...) wrote to parameter None, suite parameter None of <LegacySuite.legacy>, but the test runs as parameter None, suite parameter admin. Pass the running parameter= and suite_parameter=, or call Meta.update(**values) without self, which always writes to the running testAssignees since 0.8a.8
Have a large QA team sharing the same framework? Test Junkie lets you assign
suites and tests to specific team members via the
owner property. In the HTML report,
you'll see performance metrics broken down by assignee, and assignees are also readable from
Listeners for custom reporting. See also features,
components, and tags - the other categorization axes.
Both @Suite() and @test() support
owner. Setting it on @Suite()
assigns every test in that suite to the same owner by default; setting it again on a specific
@test() overrides the owner for just that test.
You can run only a given owner's tests with runner.run(owners=[...]) -
see running tests assigned to a specific person.
Features since 0.8a.8
Categorizing suites by the feature they cover doesn't just give you KPI metrics broken down by feature in the HTML report - it also lets you run feature-specific regression.
Features are defined via the feature property of the
@Suite() decorator - one feature per suite, but a feature can be made up
of multiple components. See also components,
tags, and assignees - the other categorization axes.
Components since 0.8a.8
Categorizing tests by the component they cover doesn't just give you KPI metrics broken down by component in the HTML report - it also lets you run component-specific regression.
Components are defined via the component property of the
@test() decorator - a feature can be made up of
several components. See also features, tags, and
assignees - the other categorization axes.
Tags since 0.8a.8
Similar to features and components, but tags are many-to-many: a single test can cover multiple areas of the platform - more than one component, even more than one feature. Ideally tests stay small and cover one thing, but in practice (especially with end-to-end tests) that's not always realistic. Tags let you tell Test Junkie, and your teammates, what a test actually covers at a glance.
Tags are supported only by the @test() decorator. Like features and components, they show up as KPI metrics in the HTML report, and let you run tag-specific regression. See also features, components, and assignees - the other categorization axes.
The tag_config argument to the Runner's
run() method controls which tags to run tests for, and which to
skip.
tag_config options
| Key | Effect |
|---|---|
run_on_match_all | Run tests matching every tag in the list |
run_on_match_any | Run tests matching at least one tag in the list |
skip_on_match_all | Skip tests matching every tag in the list |
skip_on_match_any | Skip tests matching at least one tag in the list |
All four can be set at once. Skip conditions are checked first (skip_on_match_all
or skip_on_match_any matching skips the test immediately), then run
conditions (run_on_match_all or run_on_match_any
matching runs it). If neither run condition is configured at all, a test that wasn't skipped runs
by default - you don't need to set a run condition just to get normal execution.
A skip triggers the on_skip event.
from test_junkie.runner import Runner

runner = Runner([ExampleSuite1, ExampleSuite2, ExampleSuite3])
runner.run(tag_config={"run_on_match_all": ["...", "..."],
                       "run_on_match_any": ["...", "..."],
                       "skip_on_match_all": ["...", "..."],
                       "skip_on_match_any": ["...", "..."]})
HTML report since 0.8a.8
Test Junkie tracks a number of metrics during test execution and can generate an HTML report from them.
{# Live-demo card: thumbnail of the HTML report + label, title, text, button. Styles: .demo-cta in static_src/components.css. with: text="…" (required), compact=True for a smaller thumbnail (Get Started), title="…" (default "Click through a real report"). #}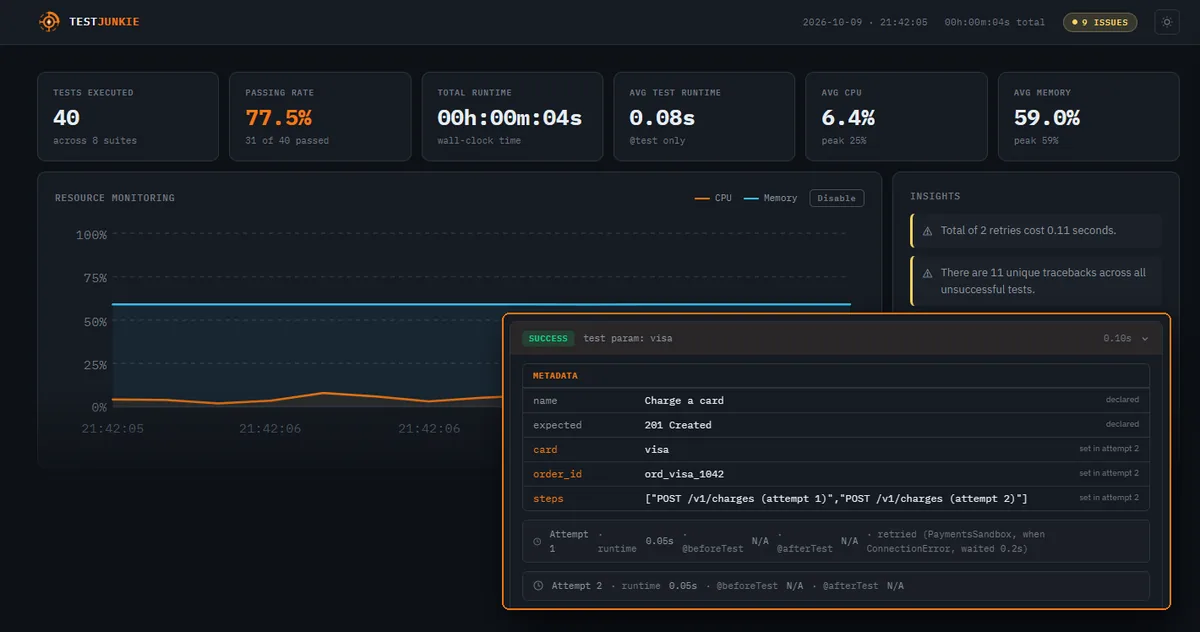
Live demo
Click through a real report
Real report from a 0.9a8 run: retries, flaky tests, per-attempt metadata, links and attachments.
Open the live demo →To generate a report like that:
from test_junkie.runner import Runner
runner = Runner(suites=[...], html_report="/path/to/file/report.html", monitor_resources=True)
runner.run()
monitor_resources=True turns on CPU & memory monitoring
during test execution, rendered in the HTML report as a trend graph. See also
XML report and JSON report for other output formats,
and meta for attaching custom data that shows up in reports.
XML report since 0.8a.8
Test Junkie can also produce a basic, Jenkins-friendly XML report.
from test_junkie.runner import Runner
runner = Runner(suites=[...], xml_report="/path/to/file/report.xml")
runner.run()
See also HTML report for a richer, visual report, and JSON report for raw data you can process yourself.
Retried and flaky tests new since 0.9a8
A retried test keeps every run in the report, in the layout Maven Surefire uses. Jenkins (with its Flaky Test Handler plugin) and other flaky-test trackers can read it, so they can tell a flaky test from a broken one.
- A test that passed after failing (a flaky test) gets a
<flakyFailure>for each run that failed and a<flakyError>for each run that errored. - A test that never passed gets
<failure>for its first run and a<rerunFailure>or<rerunError>for each retry. - Each one has the exception's
typeandmessage, and its traceback in<stackTrace>.
This is part of the report from a run with the Flaky
policy: pays_with_card timed out once and then passed, and applies_coupon
timed out on all three runs its When allows.
<testcase name="pays_with_card" status="success">
  <flakyError type="TimeoutError"
      message="payment gateway took 30s">
    <stackTrace>Traceback (most recent call last):
  ...
TimeoutError: payment gateway took 30s
</stackTrace>
  </flakyError>
</testcase>
<testcase name="applies_coupon" status="failure">
  <failure type="TimeoutError"
      message="coupon service took 30s">...
  <rerunError type="TimeoutError"
      message="coupon service took 30s">...
  <rerunError type="TimeoutError"
      message="coupon service took 30s">...
</testcase>
JSON report since 0.8a.8
JSON reports are used under the hood for all of the other reports Test Junkie produces (including the HTML report). You can use the same data to slice results in whatever way is meaningful to you.
The report data becomes available on the Aggregator object
runner.run() returns, once tests have finished executing:
from test_junkie.runner import Runner
runner = Runner(suites=[...])
aggregator = runner.run()
Raw metrics
You can access raw per-suite and per-test metrics directly from SuiteObject and TestObject:
suite_objects = runner.get_executed_suites()
for suite in suite_objects:
    test_objects = suite.get_test_objects()
    print(suite.metrics.get_metrics())
    for test in test_objects:
        print(test.metrics.get_metrics())
Aggregated reports
You can also access the same aggregated reports Test Junkie's own HTML report uses, via the
Aggregator object:
print(aggregator.get_basic_report())        # overall + per-suite pass/fail totals
print(aggregator.get_report_by_features())  # grouped by feature -> component
print(aggregator.get_report_by_tags())      # grouped by tag
print(aggregator.get_report_by_owner())     # grouped by assignee
print(aggregator.get_report_by_suite())     # grouped by suite name
suites dict is keyed by the actual SuiteObject, not a string - get_report_by_suite() is the one that groups by suite class name instead.Truncation new since 0.9a8
When a test fails, Test Junkie keeps two pieces of text about it: the exception message and the traceback. Each has its own limit, so one failure that prints a 2 MB response can't make the console, the HTML report or the JSON report unreadable.
| Exception message | Traceback | |
|---|---|---|
| What it is | str(exception), the text after the exception type, e.g. expected 200, got 500 | The whole stack: every frame from your test down to the line that raised, then the exception type and message |
| Where it shows | The one-line headline of each problem in the console, the error of each run in the JSON report, the failure message in the XML report | The detail under each problem in the console, and the HTML and XML reports |
| Gets long when | You assert on big data: assert response.json() == expected prints both dicts. Or an API returns a whole HTML error page as its message | Deep call stacks: page objects calling helpers calling Selenium or requests, recursion, chained exceptions (During handling of the above exception...) |
| Default | 3000 characters, middle | 3000 characters, middle |
| Set with | Limiter.EXCEPTION_MESSAGE_LIMITLimiter.EXCEPTION_MESSAGE_TRUNCATE--message-limit N | Limiter.TRACEBACK_LIMITLimiter.TRACEBACK_TRUNCATE--traceback-limit N |
What to keep: top, bottom or middle
When a text is over its limit, Test Junkie keeps that many characters and says how many it cut. The mode decides which characters are kept:
TRUNCATE_MIDDLE("middle", the default) keeps both ends and cuts the middle. For a traceback, that keeps your test's frame at the top and the line that raised at the bottom: the two parts you read first.TRUNCATE_TOP("top") cuts the start and keeps the end. Use it for very deep stacks where only the last frames matter.TRUNCATE_BOTTOM("bottom") cuts the end and keeps the start. Good for long messages whose first line says it all. For tracebacks it cuts off the exception line, so it's rarely what you want there.
from test_junkie.objects import Limiter

# short headlines: keep the start of each message
Limiter.EXCEPTION_MESSAGE_LIMIT = 300
Limiter.EXCEPTION_MESSAGE_TRUNCATE = "bottom"

# more of the stack, both ends (the default)
Limiter.TRACEBACK_LIMIT = 10000
Limiter.TRACEBACK_TRUNCATE = Limiter.TRUNCATE_MIDDLE
Traceback (most recent call last):
  File "tests/checkout_suite.py", line 41, in pays_with_saved_card
    page.pay(card="4242")
  File "pages/checkout_page.py", line 88, in pay
[. . . 4,210 characters cut . . .]
  File "selenium/webdriver/remote/errorhandler.py", line 229, in check_response
    raise exception_class(message, screen, stacktrace)
selenium.common.exceptions.TimeoutException: Message: pay button never became clickable
Good to know
- Only what is recorded is cut: the console, the reports and TestObject metrics. Listeners still get the full exception and traceback, so a listener that saves failures to a database keeps everything.
- A truncated exception keeps its type.
isinstance(), retry_on and the error/failure split work exactly as before. --truncate MODEandrun(truncate=)set the mode for both texts. In code they're separate. See limits for one run.Limiter.ACTIVE = Falsekeeps everything uncut.
Runner() since 0.8a.8
Runner is the object that actually executes your tests - everything
else in Test Junkie (decorators, listeners, rules) just describes what to run and how; Runner
is what runs it. Construct one with your suites, then call run().
| Constructor arg | Type | Description |
|---|---|---|
suites | list, required | Class objects decorated with @Suite() - tells Test Junkie which suites to run. |
monitor_resources | bool | Turns on CPU & memory monitoring, surfaced in the HTML report and charted in the console after the summary (resource chart). |
html_report | str | Path to write the HTML report to. Omit to skip HTML reporting. |
xml_report | str | Path to write the XML report to. Omit to skip XML reporting. |
json_report | str | Path (or folder) to write the JSON report to: every test, every run, with status, runtime and error. Omit to skip JSON reporting. |
config | str | Path to a config file (created via the CLI). Anything passed explicitly to Runner/run() overrides the config file; the file fills in whatever wasn't passed explicitly. |
from test_junkie.runner import Runner

runner = Runner([LoginSuite, CheckoutSuite], html_report="reports/run.html")
runner.run(suite_multithreading_limit=2, test_multithreading_limit=10)
run()
Every argument is optional - calling runner.run() with nothing runs everything under the suites you constructed it with, unparallelized.
| Argument | Type | Description |
|---|---|---|
features | list | Only run these features, e.g. runner.run(features=["Login"]). |
components | list | Only run these components, e.g. runner.run(components=["2FactorAuth"]). |
owners | list | Only run tests owned by these people, e.g. runner.run(owners=["John Cena"]). See assignees. |
tag_config | dict | Run/skip by tag match mode, e.g. runner.run(tag_config={"run_on_match_all": ["pre_deploy", "critical"]}). |
tests | list | Only run these tests - function objects or name strings: runner.run(tests=[LoginSuite.positive_login]) or runner.run(tests=["positive_login"]). |
suite_multithreading_limit | int | Enables parallel execution across suites. |
test_multithreading_limit | int | Enables parallel execution across tests. |
quiet | bool | Silences test output. |
retry_policy | RetryPolicy | str | A retry policy for every test that sets no retry of its own and whose suite sets no retry_policy; a class or "module:Class". |
flag_flaky | bool | Lists the flaky tests after the summary. |
fail_on_flaky | bool | A flaky test fails the run, and is listed like flag_flaky. |
test_throttling, suite_throttling, ramp_up, traceback_limit, message_limit, truncate | number / str | Throttling, ramp-up and truncation for this run only. See limits per run. |
Other methods
| Method | Description |
|---|---|
cancel() | Stops execution gracefully mid-run. See canceling tests. |
get_executed_suites() | Returns a list of SuiteObject instances - use it to analyze anything from results to performance after run() returns. |
Execution flow
The exact sequence Test Junkie calls each method — from the moment Python processes your decorator imports through the final line of runner.run(). Orange = hooks you write; grey = TJ-managed internals.
@Suite()Builder.build_suite_definitions() — class registered in the execution roster@beforeClass() @afterClass()class-level lifecycle hooks registered against the suite@beforeTest() @afterTest()per-test hooks registered against the suite@test()test case function registered (DecoratorType.TEST_CASE)@GroupRules() @beforeGroup() @afterGroup()cross-suite group rules registered in Builder__prioritize(suites)sort suites by priority; non-parallelized suites pushed to the endsuite.metrics.reset() / test.metrics.reset()suites are singletons — clear any results from a prior runBuilder.build_group_definitions()evaluates @GroupRules functions and finalizes beforeGroup/afterGroup mappingsSettings(runner_kwargs, run_kwargs)merges constructor args, run() args, and config file — run() args winResourceMonitor.start()only when monitor_resources=TrueParallelProcessor(settings)wires up suite_multithreading_limit and test_multithreading_limit@beforeGroupruns once before this suite if it belongs to a group; skipped otherwiselistener.on_class_in_progress()Rules.before_class()@beforeClassLimiter.wait_turn()parallel runs: waits for the next start slot (throttling) and a free thread (ramp-up grows the limit)listener.on_in_progress()Limiter.acquire(uses)↓ repeats for each retry attempt · takes a slot in each resource pool, given back after @afterTestRules.before_test()↓ repeats for each retry attempt@beforeTest@test ← your test code executes here@afterTestRules.after_test()ON_SUCCESS / ON_FAILURE / ON_ERRORbreaks on success; retries if still within retry_limit ↑listener.on_complete()fires regardless of outcome@afterClassRules.after_class()listener.on_class_complete()@afterGroupruns once after this suite if it belongs to a group; skipped otherwiseAggregator.present_console_output()prints the summary table to stdoutReporter.generate_html_report()only if html_report path was set on RunnerXmlReporter.create_xml_report()only if xml_report path was set on Runnerwrite_json_report()only if json_report path was set on Runner (or tj run --json-report) — what --rerun readsLimiter.end_run()puts back the limits set in codeRunning tests since 0.8a.8
Everything below is a Runner() call - the same object, just with a different
slice of arguments for each situation. Combine them freely: features,
components, owners,
tag_config, and tests all filter the
same pool of suites you constructed the Runner with.
Parallel execution
The most common starting point: run every suite you passed in, up to 5 suites and 5 tests in parallel at once. See parallel execution for how the limits interact.
from test_junkie.runner import Runner
from ... import LoginSuite, CheckoutSuite, ApiSuite

runner = Runner([LoginSuite, CheckoutSuite, ApiSuite])
runner.run(suite_multithreading_limit=5, test_multithreading_limit=5)
Regression for a feature
Out of the suites you constructed the runner with, only the ones matching the given features run - everything else is skipped.
runner = Runner(suites=[...])
runner.run(features=["Login"])
Regression for a component
Same idea, scoped to components instead of features.
runner = Runner(suites=[...])
runner.run(components=["OAuth"])
Regression for tags
Runs the tag_config match modes against every test in scope - useful for "everything critical, except known-flaky" style slices.
runner = Runner(suites=[...])
runner.run(tag_config={"run_on_match_all": ["component_a", "critical"],
                       "skip_on_match_any": ["trivial", "known_failure"]})
Tests assigned to a specific person
Scoped to owners - handy for "just run my stuff" during local development.
runner = Runner(suites=[...])
runner.run(owners=["John Doe", "Jane Doe"])
Specific tests
Pass the test functions directly if they're already imported:
runner = Runner(suites=[...])
runner.run(tests=[LoginSuite.positive_login, LoginSuite.negative_login])
...or use their names as strings if you'd rather not import them:
runner = Runner(suites=[...])
runner.run(tests=["positive_login", "negative_login"])
Canceling tests since 0.8a.8
If you're integrating Test Junkie into a bigger framework, you may want to programmatically stop test
execution - a deploy got aborted, a CI job got killed, a user hit stop in your own tooling. Calling
cancel() on the Runner does this
gracefully: it triggers on_cancel and on_class_cancel
rather than abruptly killing anything.
cancel() just flips a flag that run() checks internally as it goes. Since run() doesn't return until the whole cycle is done (or canceled), you can't call it and then cancel() on the next line - that line never executes until it's already too late. Call cancel() from a separate thread, or from whatever external signal (a timeout, a kill switch) tells you to stop.import threading from test_junkie.runner import Runner from ... import LoginSuite, CheckoutSuite, ApiSuite runner = Runner([LoginSuite, CheckoutSuite, ApiSuite]) threading.Thread(target=runner.run, kwargs={"suite_multithreading_limit": 5}).start() # elsewhere, once something tells you to abort: runner.cancel()
Tests that are already running when you cancel finish their current run and aren't retried since 0.9a6
. Pressing Ctrl+C during tj run, or during run() on the main thread, cancels the same way. See Stopping a run with Ctrl+C.
How a cancelled run ends new since 0.9a8
- The run ends
[CANCELLED]and exits with code 12, even if tests had already failed. Ctrl+C andRunner.cancel()end the same way. - Suites the cancel came before list their tests as cancelled, in every mode, so the JSON and HTML totals match the console.
- A suite with a cancelled test is
cancel, notsuccess. A suite with a failed, errored or ignored test staysfail. A cancelled test doesn't count as unsuccessful. - A
KeyboardInterruptraised by a hook or listener cancels the run like Ctrl+C, but @afterClass() and @afterGroup() still run.
SuiteObject() since 0.8a.8
Every listener event - on_in_progress,
on_failure, on_complete, and the rest -
hands you the suite's SuiteObject in its kwargs. It's your read
access into what the suite is doing right now: how many tests it has, who owns it, what its current
pass/fail counts are. Reach for it when a listener needs to make a decision based on the suite as a
whole rather than just the one test that triggered the event - failing the build once a suite crosses
an error threshold, or routing an alert to the right owner.
from test_junkie.listener import Listener

class MyTestListener(Listener):

    def __init__(self, **kwargs):
        Listener.__init__(self, **kwargs)

    def on_failure(self, **kwargs):
        properties = kwargs.get("properties")
        suite = properties["jm"]["jso"]
        # suite is the SuiteObject for whichever suite just failed a test
        if suite.has_unsuccessful_tests() and suite.get_owner() == "artur":
            send_alert(suite.get_class_name(), suite.get_owner())
total = int(suite.get_test_count())), but mutating a returned list/dict/set in place can corrupt the run TJ is still executing. Copy first (copy.deepcopy(...)) if you need to modify it.Methods
Every getter takes no arguments unless noted. Jump straight to a row via its link in the sidebar-linked sections below, or scan the table.
| Method | Returns | Description |
|---|---|---|
get_test_count() | int | Number of test functions in the suite. Doesn't multiply out by parameters - one parameterized test still counts as 1. |
get_class_name() | str | Name of the suite class, e.g. "ExampleSuite". |
get_class_instance() | object | The live instance of your suite class - lets a listener read/set instance attributes your tests use. |
get_class_object() | class | The class itself, not an instance of it (compare to get_class_instance). |
get_class_module() | str | Python module path the suite class is defined in. |
get_test_objects() | list | Every TestObject in this suite. |
get_test_function_names() | list[str] | Same as get_test_objects, but just the function names. |
get_test_components() | set | Every component covered by a test in this suite. Includes None if any test left it undefined. |
get_test_tags() | set | Every tag used by a test in this suite. |
get_feature() | str | None | The suite's feature. A suite has exactly one; a feature can span several suites. |
get_priority() | int | None | The suite's priority, or None if it wasn't set. |
get_runtime() | float | Seconds the suite has been running, updated live. |
get_retry_limit() | int | The suite-level retry limit. Defaults to 1 (no retries). |
get_meta(copy_of_meta=False) | dict | The suite's meta dict. Pass copy_of_meta=True to get a safe deep copy instead of the live reference. |
get_unsuccessful_tests() | list | The TestObjects that are currently fail/error/ignore, deduplicated across parameters. |
has_unsuccessful_tests() | bool | Cheaper than checking len(get_unsuccessful_tests()) when you just need a yes/no. |
get_status() | str | The suite's current aggregate status: "success", "fail", "cancel", or "skip"/"ignore" for a suite skipped or ignored as a whole. A suite with any cancelled test is "cancel", unless a test failed, errored or was ignored, which makes it "fail". |
get_owner() | str | None | The suite's owner, read from meta - equivalent to get_meta()["owner"] but returned as a plain string. |
get_parallel_restrictions() | list | Other suites this one is configured never to run alongside (conflicts_with, formerly pr). |
get_parameters(process_functions=False) | list | The suite's parameters. Pass process_functions=True if your suite uses a function as its parameter provider and you want the evaluated list back, not the function object. |
is_parallelized() | bool | Whether this suite is eligible to run alongside other suites under parallel execution. |
get_data_by_tags() | dict | Pass/fail/skip/retry counts and timing, broken down per tag, plus a _totals_ bucket for the whole suite. See the example below. |
get_data_by_tags() output
The one method above worth seeing a full example of - everything else returns a plain value. Each tag gets its own bucket with the same shape as _totals_; a test with no tags is grouped under null.
{
  "_totals_": {
    "performance": [0.0, 0.0, 0.001, 0.0, 0.0, 0.0],
    "exceptions": ["AssertionError()"],
    "retries": [2, 2, 1],
    "total": 6, "success": 2, "skip": 0,
    "fail": 4, "cancel": 0, "ignore": 0, "error": 0
  },
  "login": { "... same shape, scoped to tests tagged 'login' ..." },
  "smoke": { "... same shape, scoped to tests tagged 'smoke' ..." }
}
TestObject() since 0.8a.8
Every listener event hands you the test's TestObject alongside the SuiteObject it belongs to. Where SuiteObject answers questions about the suite as a whole, TestObject answers them for the one test that triggered the event - who owns it, whether it's about to retry, whether it's parameterized. Reach for it when a listener's behavior should depend on the specific test, not just the suite around it.
from test_junkie.listener import Listener

class MyTestListener(Listener):

    def __init__(self, **kwargs):
        Listener.__init__(self, **kwargs)

    def on_failure(self, **kwargs):
        properties = kwargs.get("properties")
        test = properties["jm"]["jto"]
        # test is the TestObject for whichever test just failed
        owner = str(test.get_owner())
        if test.is_qualified_for_retry():
            log.info("%s will retry, notifying %s" % (test.get_function_name(), owner))
owner = str(test.get_owner())); mutating a returned list/dict in place isn't. Copy first if you need to change it.@beforeTest() and @afterTest() hooks, and Rules, can get the same test too, as a read-only view: its getters return copies, so nothing they do changes the run.
Methods
| Method | Returns | Description |
|---|---|---|
get_function_name() | str | Name of the test function, e.g. "example_test". |
get_function_module() | str | Module the test function is defined in - useful for routing an alert from a listener back to the right file. |
get_owner() | str | None | The test's owner, or None if it wasn't set. |
get_priority() | int | None | The test's priority, or None. |
get_component() | str | None | The component this test validates, if one was set. |
get_tags() | list | The test's tags, or an empty list. |
get_parameters(process_functions=False) | list | The test's parameters. Pass process_functions=True to evaluate a function-based parameter provider and get the concrete list back instead of the function object. |
get_retry_policy() | RetryPolicy | None | The retry policy this test retries with: @test(retry=Policy), else @Suite(retry_policy=), else the run's --retry-policy. None for a test that sets retry=N. |
get_meta_attempts(parameter=None, class_parameter=None) | list | What Meta.update() set in each run of that combination, oldest first: {"attempt", "meta_set"}. Runs that set nothing aren't listed. |
get_retry_limit() | int | The test's retry limit. Defaults to 1 (no retries). |
get_parallel_restrictions() | list | Other tests/suites this test is configured never to run alongside (conflicts_with, formerly pr). |
is_parallelized() | bool | Whether this test can run in parallel with others. Defaults to True - opt out with @test(parallelized=False). |
parallelized_parameters() | bool | Whether this test's own parameters run concurrently with each other rather than sequentially. Defaults to False, set via @test(parallelized_parameters=True). |
get_retry_on() / get_no_retry_on() | list | The exception types passed to retry_on / no_retry_on, or an empty list if neither was set. |
is_qualified_for_retry(param=None, class_param=None) | bool | The live decision behind retry_on / no_retry_on: True if this parameter combination hasn't run yet, or failed with an exception type that isn't excluded. |
get_status(param, class_param) | str | None | Current status for this test/class-parameter combination, or None if it hasn't produced a result yet. An unparameterized test uses None for both arguments. |
get_number_of_actual_retries(param, class_param) | int | How many times this parameter combination has actually been retried so far. |
is_flaky(parameter=None, suite_parameter=None) | bool | Whether this parameter combination passed only after failing or erroring in this run. See flaky tests. |
get_flaky() | list | Every flaky combination in this run: {"parameter", "suite_parameter", "passed_on_run", "errors"}. |
can_skip() | bool | Evaluates the skip condition right now - the live computed answer, not just the literal skip kwarg (which can itself be a callable). |
accepts_suite_parameters() | bool | Whether the test function's signature declares a suite_parameter argument - see Parameters. The sibling accepts_test_parameters() answers the same for a plain parameter argument. |